

Page 1
SPSS Regression Models™ 13.0
Page 2
For more information about SPSS®software products, please visit our Web site at http://www.spss.com or contact
SPSS Inc.
233 South Wacker Drive, 11th Floor
Chicago, IL 60606-6412
Tel: (312) 651
Fax: (312) 651-3668
SPSS is a registered trademark and t he other product names are the t rademarks of SPSS Inc. for its proprietary computer
software. No m
the trademark and license rights in the software and the copyrights in the published materials.
The SOFTWARE and documentation are provided with RESTRICTED R IGHTS. Use, duplication , or disclosure by the
Governmentis
clause at 52.227-7013. Contractor/manufacturer is SPSS Inc., 233 South Wacker Drive, 11th Floor, Chicago, IL 60606-6412.
General notice: Other product names mentioned herein are used for identification purposes only and may be trademarks of
their respec
TableLook is a trademark of SPSS Inc.
Windows is a registered trademark of Microsoft Corporation.
DataDirect, D
Portions of this product were created using LEADTOOLS © 1991–2000, LEAD Technologies, Inc. ALL RIGHTS RESERVED.
LEAD, LEADTOOLS, and LEADVIEW are registered trademarks of LEAD Technologies, Inc.
Sax Basic is a t
All rights reserved.
Portions of this product were based on the work of the FreeType Team (http://www.freetype.org).
A portion of th
software is provided “as is,” without express or implied warranty.
A portion of the SPSS software contains Sun Java Runtime libraries. Copyright © 2003 by Sun Microsystems, Inc. All rights
reserved. The
licensed from IBM and are available at http://oss.software.ibm.com/icu4j/.
SPSS Regression Models™ 13.0
Copyright © 20
All rights reserved.
Printed in the United States of America.
No part of this p
electronic, mechanical, photocopying, recording, or otherwise, without the prior written permission of the publisher.
1234567890 060504
ISBN 0-13-185
-3000
aterial describing such software may be produced or distributed without the written permission of the owners of
subject to restrictions as set forth in subdivision (c) (1) (ii) of The Rights in Technical Data and Computer Software
tive companies.
ataDirect Connect, INTERSOLV,and SequeLink are registered trademarks of DataDirect Technologies.
rademark of Sax Software Corporation. Copyright © 1993–2004 by Polar Engineering and Consulting.
e SPSS software contains zlib technology. Copyright © 1995–2002 by Jean-loup Gailly and Mark Adler. The zlib
Sun Java Runtime libraries include code licensed from RSA Security, Inc. Some portions of the libraries are
04 by SPSS Inc.
ublication may be reproduced, stored in a retrieval system, or transmitted, in any form or by any means,
724-X
Page 3
Preface
SPSS 13.0 is a comprehensive system for analyzing data. The Regression Models
optional a
manual. The Regression Models add-on module must be used with the SPSS 13.0
Basesystemandiscompletelyintegratedintothatsystem.
Installation
To install the Regression Models add-on module, run the License Authorization
Wizard using the authorization code that you received from SPSS Inc. For more
informat
Compatibility
SPSS is designed to run on many computer systems. See the installation instructions
that cam
requirements.
dd-on module provides the additional analytic techniques described in this
ion, see the installation instructions supplied with the SPSS Base system.
e with your system for specific information on minimum and recommended
Serial N
Your ser
this serial number when you contact SPSS Inc. for information regarding support,
payment, or an upgraded system. The serial number was provided with your Base
system
Customer Service
If you have any questions concerning your shipment or account, contact your local
office
your serial number ready for identification.
umbers
ial number is your identification number with SPSS Inc. You will need
.
, listed on the SPSS Web site at http://www.spss.com/worldwide. Please have
iii
Page 4
Training Seminars
SPSS Inc. provides both public and onsite training seminars. All seminars feature
hands-on workshops. Seminars will be offered in major cities on a regular basis. For
more informa
tion on these seminars, contact your local office, listed on the SPSS
Web site at http://www.spss.com/worldwide.
Technical S
The service
upport
s of SPSS Technical Support are available to registered customers.
Customers may contact Technical Support for assistance in using SPSS or for
installation help for one of the supported hardware environments. To reach Technical
Support, s
ee the SPSS Web site at http://www.spss.com, or contact your local office,
listedontheSPSSWebsiteathttp://www.spss.com/worldwide.Bepreparedto
identify yourself, your organization, and the serial number of your system.
Additional Publications
Additional copies of SPSS product manuals may be purchased directly from SPSS
Inc. Visit the SPSS Web Store at http://www.spss.com/estore, or contact your local
SPSS offi
ce, listed on the SPSS Web site at http://www.spss.com/worldwide.For
telephone orders in the United States and Canada, call SPSS Inc. at 800-543-2185.
For telephone orders outside of North America, contact your local office, listed
on the SP
SS Web site.
The SPSS Statistical Procedures Companion, by Marija Norušis, has been
published by Prentice Hall. A new version of this book, updated for SPSS 13.0, is
planned
.TheSPSS Advanced Statistical Procedures Companion, also based on SPSS
13.0, is forthcoming. The SPSS Guide to Data Analysis forSPSS13.0isalsoin
development. Announcements of publications available exclusively through Prentice
Hall wi
your home country, and then click
ll be available on the SPSS Web site at http://www.spss.com/estore (select
Books).
Tel l Us
Your co
Your Thoughts
mments are important. Please let us know about your experiences with SPSS
products. We especially like to hear about new and interesting applications using
the SPSS system. Please send e-mail to [email protected] or write to SPSS Inc.,
iv
Page 5
Attn.: Director of Product Planning, 233 South Wacker Drive, 11th Floor, Chicago,
IL 60606-6412.
About This Manual
This manual documents the graphical user interface for the procedures included in
the Regression Models add-on module. Illustrations of dialog boxes are taken from
SPSS for Win
dows. Dialog boxes in other operating systems are similar. Detailed
information about the command syntax for features in this module is provided in the
SPSS Command Syntax Reference, available from the Help menu.
Contacting SPSS
If you would like to be on our mailing list, contact one of our offices, listed on our
Web site at http://www.spss.com/worldwide.
v
Page 6
Page 7
Contents
1 Choosing a P
rocedure for Binary Logistic
Regression Models 1
2 Logistic Regression 3
Logistic
Logistic
Logistic
Logistic
Logistic
LOGISTIC
RegressionSetRule.................................... 6
RegressionVariableSelectionMethods..................... 6
RegressionDefineCategoricalVariables.................... 7
RegressionSaveNewVariables .......................... 9
RegressionOptions.................................... 10
REGRESSIONCommandAdditionalFeatures................ 11
3 Multinomial Logistic Regression 13
Multino
Multino
Multino
Multino
Multino
Multino
NOMREG C
mialLogisticRegressionModels........................... 15
mial Logistic Regression Reference Category . . . . . . . . . . . . . . . . . 17
mialLogisticRegressionStatistics ......................... 18
mialLogisticRegressionCriteria........................... 20
mialLogisticRegressionOptions........................... 21
mialLogisticRegressionSave............................. 23
ommandAdditionalFeatures........................... 24
vii
Page 8
4 Probit Analy
ProbitAnalysisDefineRange................................... 27
ProbitAnalysisOptions........................................ 28
PROBITCommandAdditionalFeatures............................ 29
sis 25
5 Nonlinear
ConditionalLogic(NonlinearRegression).......................... 33
NonlinearRegressionParameters ............................... 34
NonlinearRegressionCommonModels ........................... 35
NonlinearRegressionLossFunction.............................. 36
NonlinearRegressionParameterConstraints....................... 37
NonlinearRegressionSaveNewVariables......................... 38
NonlinearRegressionOptions .................................. 38
InterpretingNonlinearRegressionResults......................... 39
NLRCommandAdditionalFeatures............................... 40
6 Weight Es
WeightEstimationOptions..................................... 44
WLSCommandAdditionalFeatures .............................. 44
7Two-Sta
ge Least-Squares Regression 45
Regression 31
timation 41
Two-StageLeast-SquaresRegressionOptions...................... 47
2SLSCommandAdditionalFeatures.............................. 47
viii
Page 9
Appendix
A Categorical Variable Coding Schemes 49
Deviation
Simple .................................................... 50
Helmert ................................................... 51
Differenc
Polynomia
Repeated.................................................. 5
Special ................................................... 54
Indicator
.................................................. 49
e ................................................. 52
l................................................. 52
.................................................. 55
Index 57
3
ix
Page 10
Page 11
Chapter
1
ChoosingaPr
ocedure for
Binary Logistic Regression Models
Binary log
procedure or the Multinomial Logistic Regression procedure. Each procedure has
options not available in the other. An important theoretical distinction is that the
Logistic R
and goodness-of-fit tests using data at the individual case level, regardless of how the
data are entered and whether or not the number of covariatepatterns is smaller than the
total num
aggregates cases to form subpopulations with identical covariate patterns for the
predictors, producing predictions, residuals, and goodness-of-fit tests based on these
subpopu
on only a limited number of values—so that there are several cases at each distinct
covariate pattern—the subpopulation approach can produce valid goodness-of-fit tests
and inf
istic regression models can be fitted using either the Logistic Regression
egression procedure produces all predictions, residuals, influence statistics,
ber of cases, while the Multinomial Logistic Regression procedure internally
lations. If all predictors are categorical or any continuous predictors take
ormative residuals, while the individual case level approach cannot.
ic Regression
Logist
Hosme
Stepw
Contra
Altern
Classi
Model f
Saves p
fication plots
provides the following unique features:
r-Lemeshow test of goodness of fit for the model
ise analyses
sts to define model parameterization
ative cut points for classification
itted on one set of cases to a held-out set of cases
redictions, residuals, and influence statistics
1
Page 12
2
Chapter 1
Multinomial Logistic Regression provides the following unique features:
Pearson and deviance chi-square tests for goodness of fit of the model
Specification of subpopulations for grouping of data for goodness-of-fit tests
Listing of counts, predicted counts, and residuals by subpopulations
Correction of variance estimates for over-dispersion
Covariance matrix of the parameter estimates
Tests of linear combinations of parameters
Explicit specification of nested models
Fit 1-1 matched conditional logistic regression models using differenced variables
Page 13
Chapter
2
Logistic Reg
Logistic regression is useful for situations in which you want to be able to predict
the presenc
predictor variables. It is similar to a linear regression model but is suited to models
where the dependent variable is dichotomous. Logistic regression coefficients can
be used to e
Logistic regression is applicable to a broader range of research situations than
discriminant analysis.
Example.
(CHD)? Given a sample of patients measured on smoking status, diet, exercise,
alcohol use, and CHD status, you could build a model using the four lifestyle variables
to predic
then be used to derive estimates of the odds ratios for each factor to tell you, for
example, how much more likely smokers are to develop CHD than nonsmokers.
Statist
categorical variable: parameter coding. For each step: variable(s) entered or
removed, iteration history, –2 log-likelihood, goodness of fit, Hosmer-Lemeshow
goodne
table, correlations between variables, observed groups and predicted probabilities
chart, residual chi-square. For each variable in the equation: coefficient (B), standard
error o
exp(B), log-likelihood if term removed from model. For each variable not in the
equation: score statistic. For each case: observed group, predicted probability,
predi
e or absence of a characteristic or outcome based on values of a set of
stimate odds ratios for each of the independent variables in the model.
What lifestyle characteristics are risk factors for coronary heart disease
t the presence or absence of CHD in a sample of patients. The model can
ics.
For each analysis: total cases, selected cases, valid cases. For each
ss-of-fit statistic, model chi-square, improvement chi-square, classification
f B, Wald statistic, estimated odds ratio (exp(B)), confidence interval for
cted group, residual, standardized residual.
ression
Methods. You can estimate models using block entry of variables or any of the
following stepwise methods: forward conditional, forward LR, forward Wald,
ard conditional, backward LR, or backward Wald.
backw
3
Page 14
4
Chapter 2
Data. The dependent variable should be dichotomous. Independent variables can be
interval level or categorical; if categorical, they should be dummy or indicator coded
(there is an
Assumptions. Logistic regression does not rely on distributional assumptions in the
option in the procedure to recode categorical variables automatically).
same sense that discriminant analysis does. However, your solution may be more
stable if yo
ur predictors have a multivariate normal distribution. Additionally, as
with other forms of regression, multicollinearity among the predictors can lead to
biased estimates and inflated standard errors. The procedure is most effective when
group memb
ership is a truly categorical variable; if group membership is based
on values of a continuous variable (for example, “high IQ” versus “low IQ”), you
should consider using linear regression to take advantage of the richer information
offered b
Related procedures. Use the Scatterplot procedure to screen your data
y the continuous variable itself.
for multicollinearity. If assumptions of multivariate normality and equal
variance
-covariance matrices are met, you may be able to get a quicker solution using
the Discriminant Analysis procedure. If all of your predictor variables are categorical,
you can also use the Loglinear procedure. If your dependent variable is continuous,
use the L
inear Regression procedure. You can use the ROC Curve procedure to plot
probabilities saved with the Logistic Regression procedure.
Obtain
E From th
Analyze
Regression
Binary Logistic...
ing a Logistic Regression Analysis
e menus choose:
Page 15
5
Logistic Regre
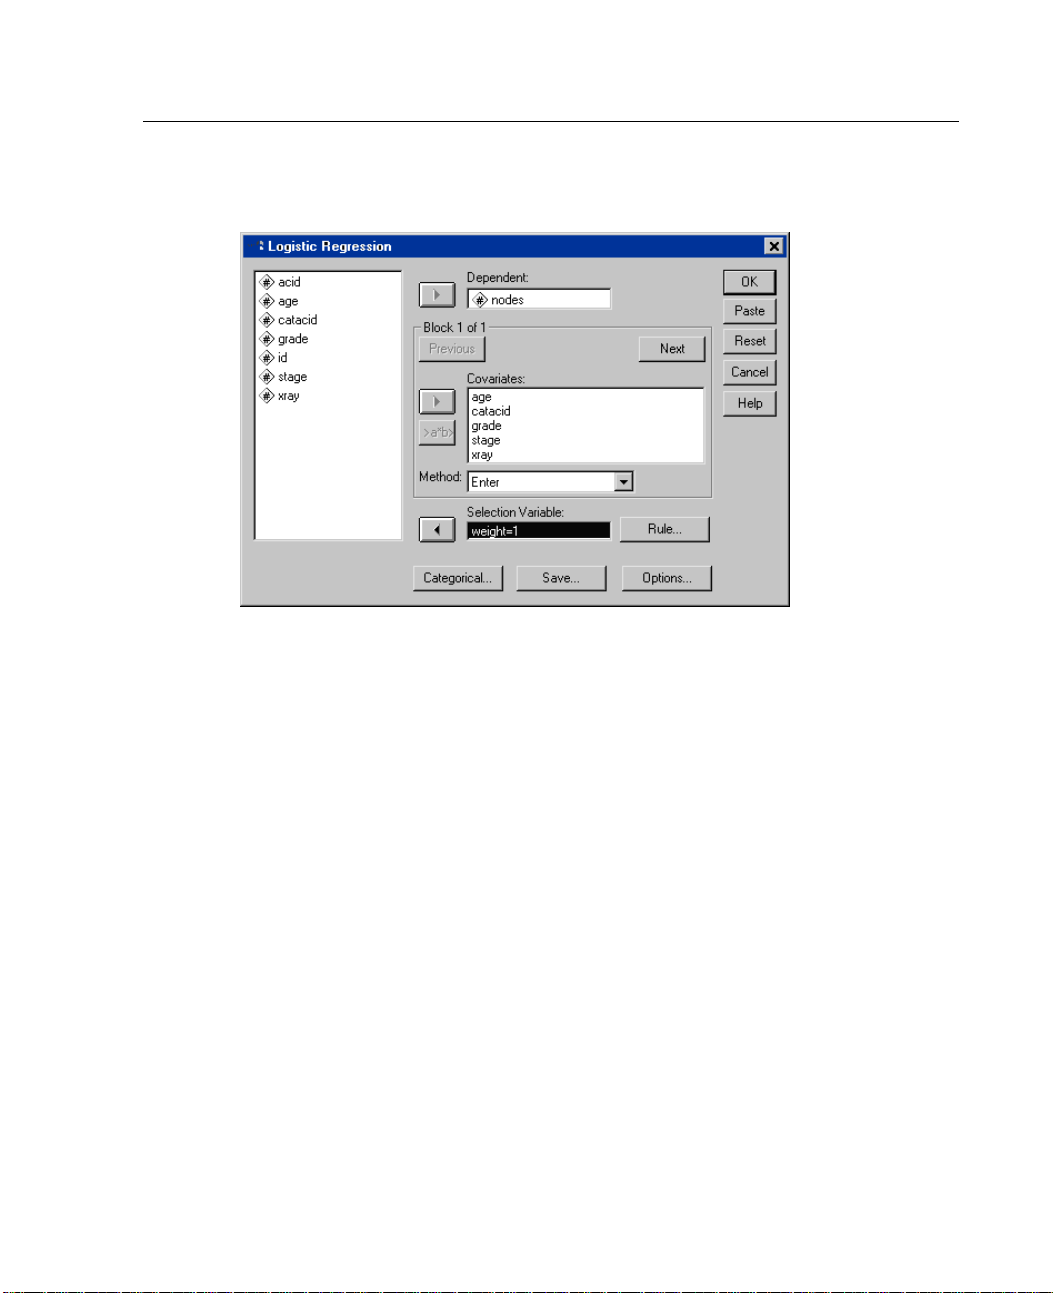
Figure 2-1
Logistic Regression dialog box
E Select one dichotomous dependent variable. This variable may be numeric or short
ssion
string.
E Select one or more covariates. To include i nteraction terms, select all of the variables
involved in the interaction and then select >a*b>.
To enter variables in groups (blocks), select the covariates for a block, and click
Next
to specify a new block. Repeat until all blocks have been specified.
Optionally, you can select cases for analysis. Choose a selection variable, and click
Rule.
Page 16
6
Chapter 2
Logistic Reg
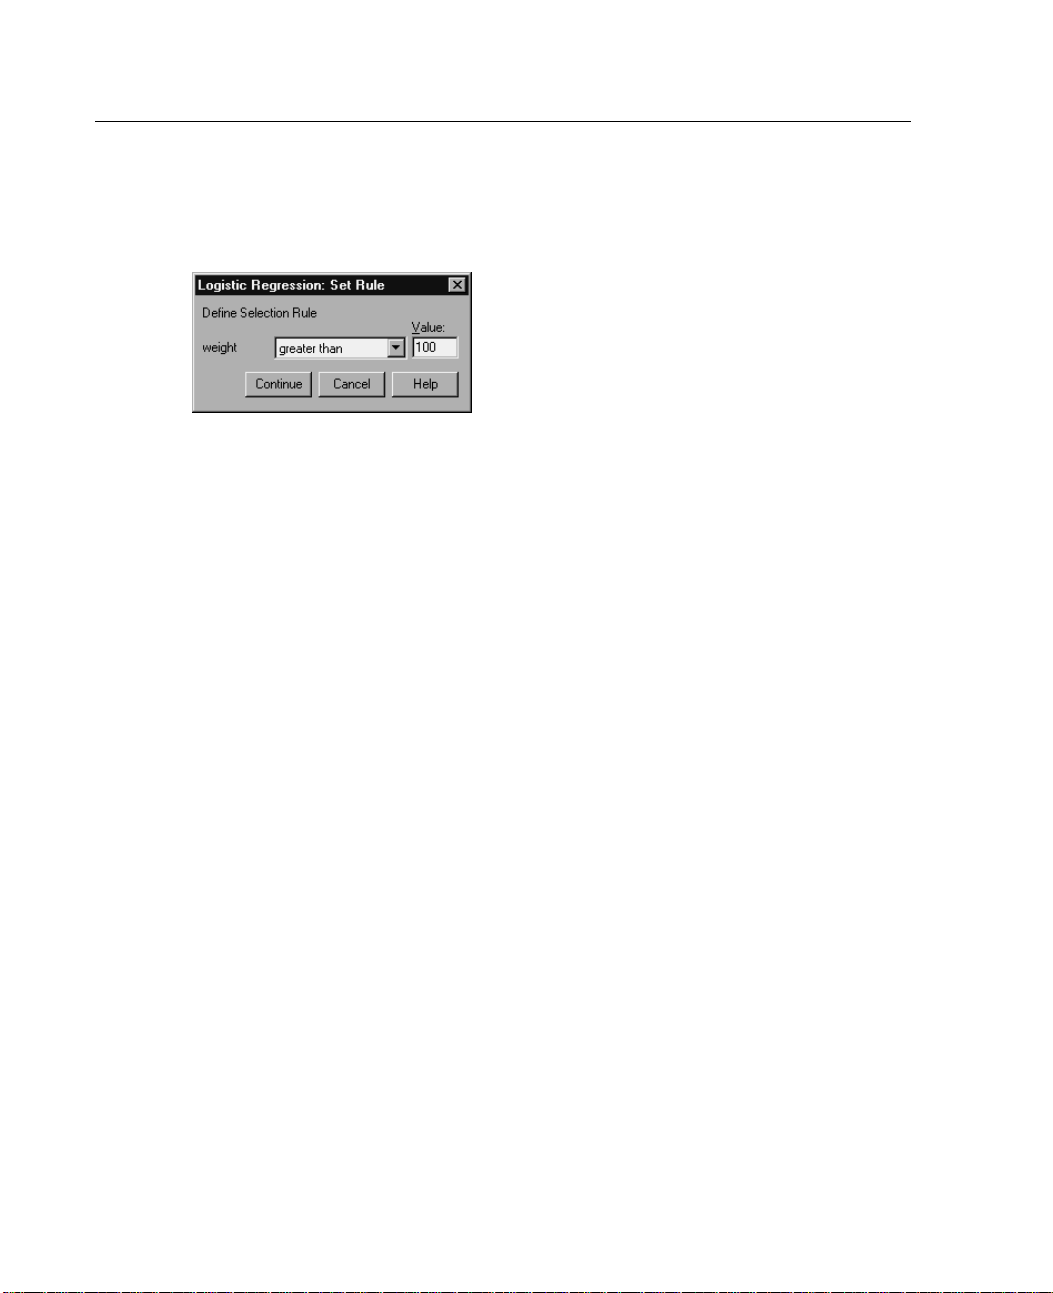
Figure 2-2
Logistic Regression Set Rule dialog box
Cases defi
youselectedavariableand
which the selected variable has a value equal to 5 are included in estimating the model.
cases. This provides a mechanism for classifying new cases based on previously
existing data, or for partitioning your data into training and testing subsets, to perform
validati
ression Set Rule
ned by the selection rule are included in model estimation. For example, if
Statistic
s and classification results are generated for both selected and unselected
on on the model generated.
equals and specified a value of 5, then only the cases for
Logistic Regression Variable Selection Methods
Method selection allows you to specify how independent variables are entered into
the anal
models from the same set of variables.
Enter. A procedure for variable selection in which all variables in a block are
Forwar
Forward Selection (Likelihood Ratio). Stepwiseselectionmethodwithentry
Forward Selection ( Wald). Stepwise selection method with entry testing based
ysis. Using different methods, you can construct a variety of regression
entered
based on the significance of the score statistic, and removal testing based on the
probability of a likelihood-ratio statistic based on conditional parameter estimates.
testin
on the probability of a likelihood-ratio statistic based on the maximum partial
likelihood estimates.
on the s
probability of the Wald statistic.
in a single step.
d Selection (Conditional).
g based on the significance of the score statistic, and removal testing based
ignificance of the score statistic, and removal testing based on the
Stepwise selection method with entry testing
Page 17
7
Backward Elimination (Conditional). Backward stepwise selection. Removal
testing is b
ased on the probability of the likelihood-ratio statistic based on
conditional parameter estimates.
Backward Elimination (Likelihood Ratio). Backward stepwise selection. Removal
testing is based on the probability of the likelihood-ratio statistic based on the
maximum par
Backward E
tial likelihood estimates.
limination (Wald).
Backward stepwise selection. Removal testing is
based on the probability of the Wald statistic.
The significance values in your output are based on fitting a single model. Therefore,
the signif
icance values are generally invalid when a stepwise method is used.
All independent variables selected are added to a single regression model.
However, you can specify different entry methods for different subsets of variables.
For exampl
e, you can enter one block of variables into the regression model using
stepwise selection and a second block using forward selection. To add a second block
of variables to the regression model, click
Next.
Logistic Regression Define Categorical Variables
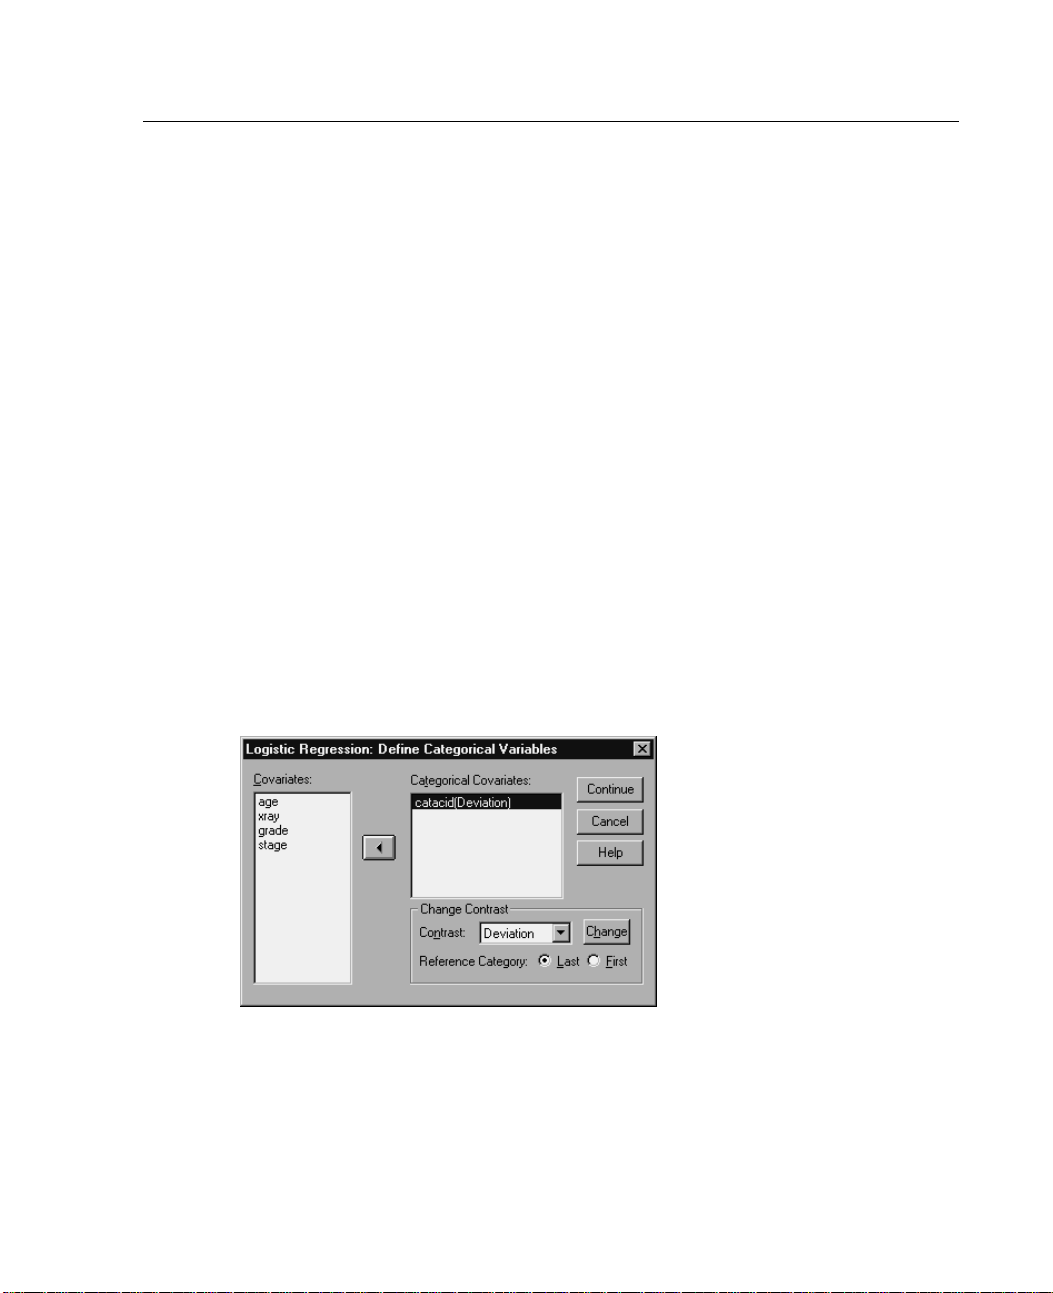
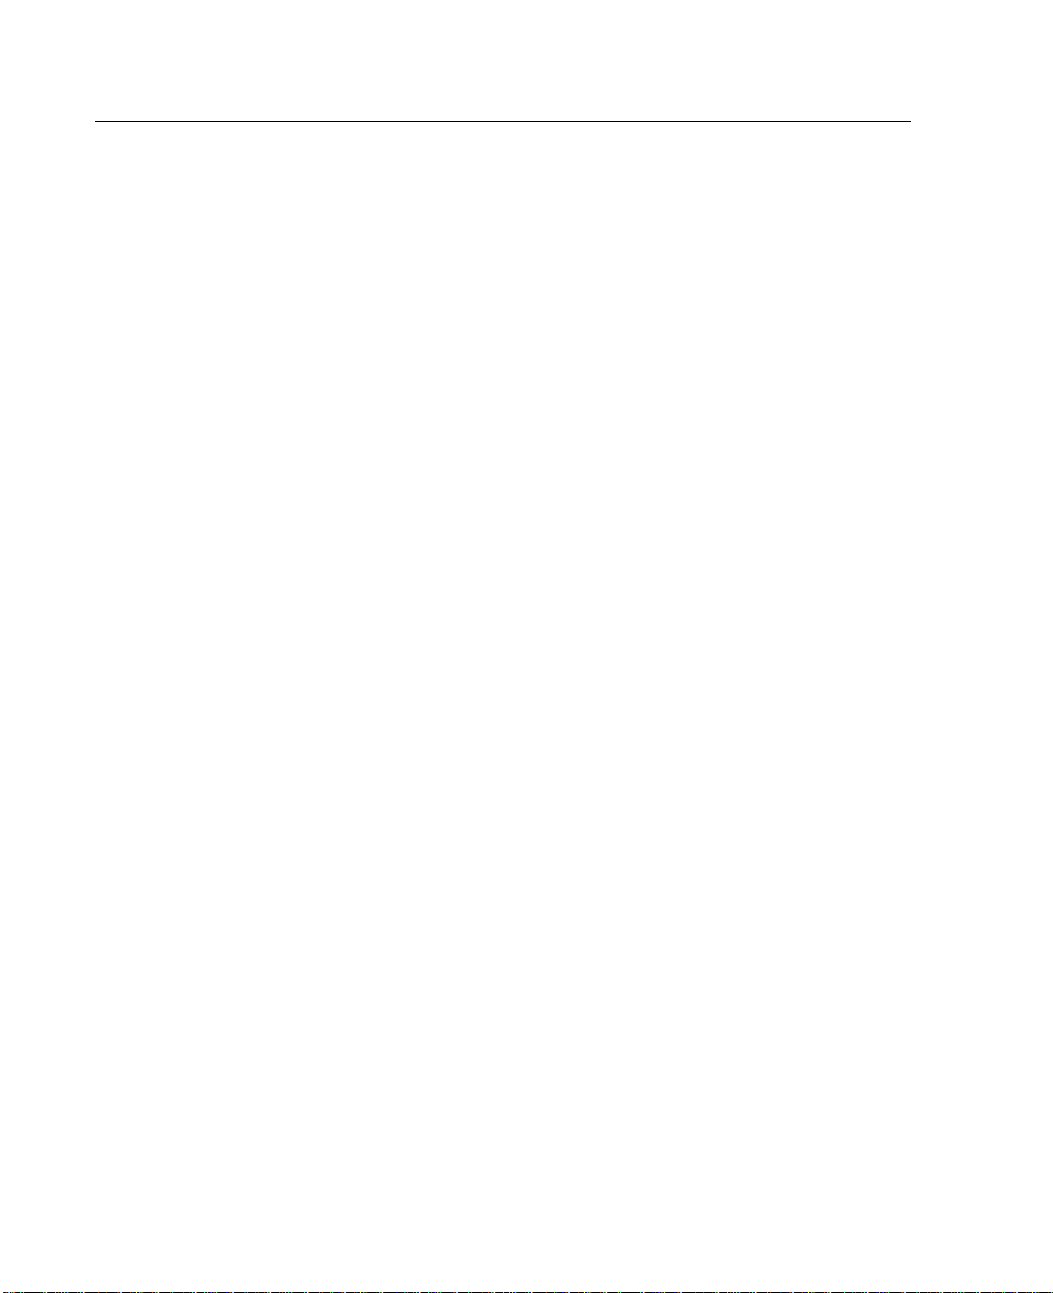
Figure 2-
Logistic
3
Regression Define Categorical Variables dialog box
Logistic Regre
ssion
Page 18
8
Chapter 2
You can specify details of how the Logistic Regression procedure will handle
categorical variables:
.
Covariates
Contains a list of all of the covariates specified in the main dialog box,
either by themselves or as part of an interaction, in any layer. If some of these are
string variables or are categorical, you can use them only as categorical covariates.
Categorica
l Covariates.
Lists variables identified as categorical. Each variable
includes a notation in parentheses indicating the contrast coding to be used. String
variables (denoted by the symbol < following their names) are already present in
the Catego
rical Covariates list. Select any other categorical covariates from the
Covariates list and move them into the Categorical Covariates list.
Change Contrast. Allows you to change the contrast method. Available contrast
methods ar
Indicato
e:
r.
Contrasts indicate the presence or absence of category membership.
The reference category is represented in the contrast matrix as a row of zeros.
Simple. Each category of the predictor variable (except the reference category) is
compared to the reference category.
Difference. Each category of the predictor variable except the first category is
compared
to the average effect of previous categories. Also known as reverse
Helmert contrasts.
Helmert. Each category of the predictor variable except the last category is
compared to the average effect of subsequent categories.
Repeated. Each category of the predictor variable except the first category is
compared
Polynom
to the category that precedes it.
ial.
Orthogonal polynomial contrasts. Categories are assumed to be
equally spaced. Polynomial contrasts are available for numeric variables only.
Deviation. Each category of the predictor variable except the reference category is
compared to the overall effect.
If you select Deviation, Simple,orIndicator, select either First or Last as the reference
categor
y. Note that the method is not actually changed u ntil you click
Change.
String covariates must be categorical covariates. To remove a string variable from
the Categorical Covariates list, you must remove all terms containing the variable
from the
Covariates list in the main dialog box.
Page 19
9
Logistic Reg
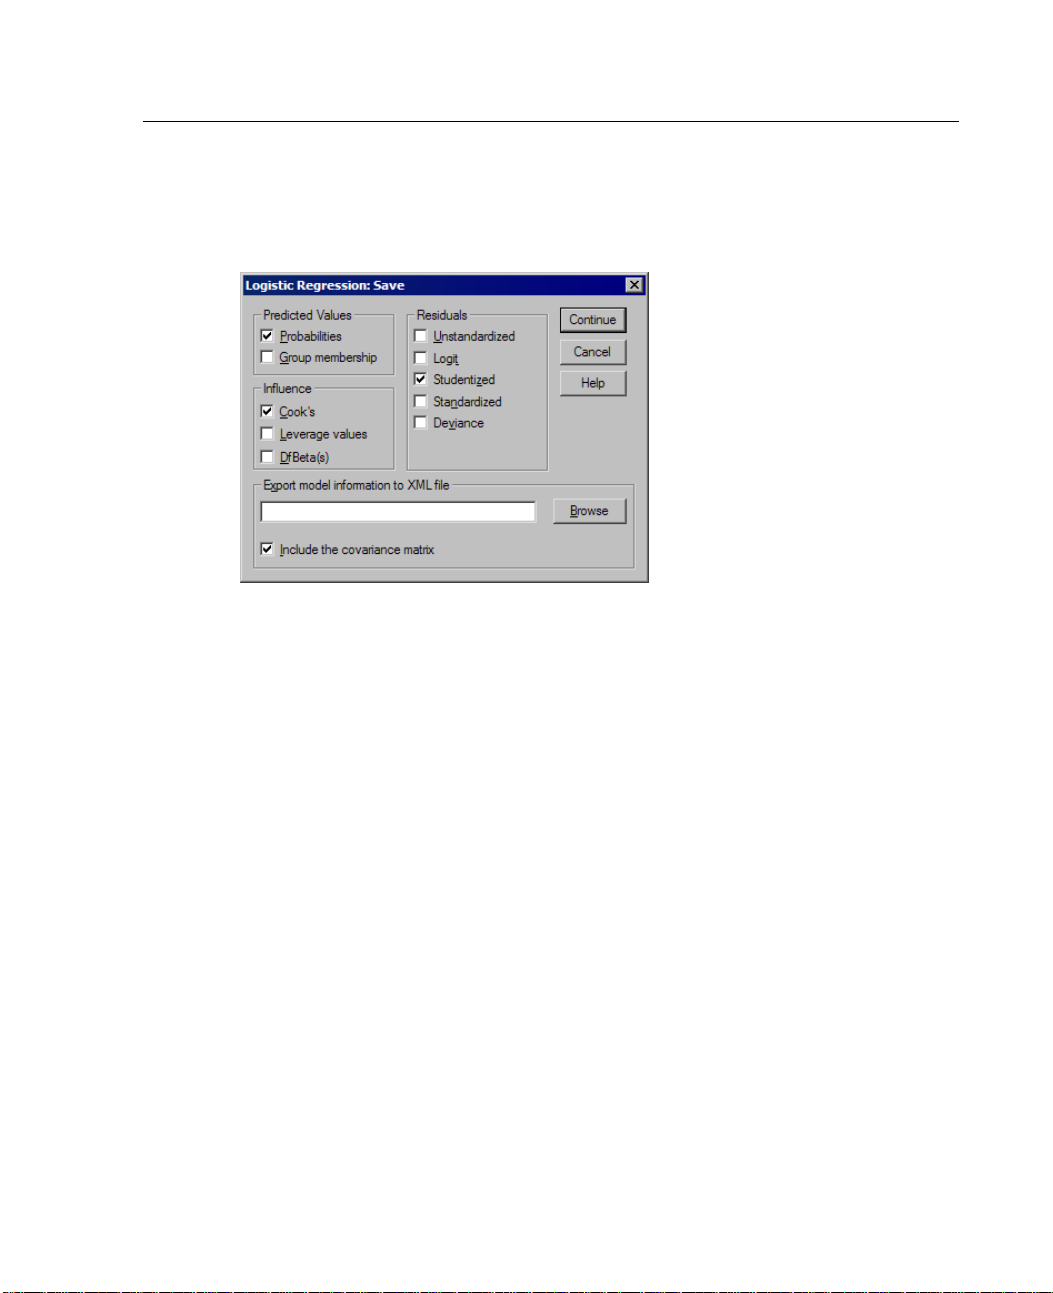
Figure 2-4
Logistic Regression Save New Variables dialog box
You can save results of the logistic regression as new variables in the working data file:
Predicted Values. Saves values predicted by the model. Available options are
Probabilities and Group membership.
Probabilities. For each case, saves the predicted probability of occurrence of the
event. A table in the output displays name and contents of any new variables.
Predicted Group Membership. The group with the largest posterior probability,
based on discriminant scores. The group the model predicts the case belongs to.
ression Save New Variables
Logistic Regre
ssion
Influence. Saves values from statistics that measure the influence of cases on predicted
values. Available options are Cook’s, Leverage values, and DfBeta(s).
Cook's. The logistic regression analog of Cook's influence statistic. A measure
of how much the residuals of all cases would change if a particular case were
excluded from the calculation of the regression coefficients.
Leverage Value. The relative influence of each observation on the model's fit.
DfBeta(s). The difference in beta value is the change in the regression coefficient
that results from the exclusion of a particular case. A value is computed for each
term in the model, including the constant.
Residuals. Saves residuals. Available options are Unstandardized, Logit, Studentized,
Standardized, and Deviance.
Page 20
10
Chapter 2
Unstandardized Residuals. The difference between an observed value and the
value predi
Logit Resid
cted by the model.
ual.
The residual for the case if it is predicted in the logit scale. The
logit residual is the residual divided by the predicted probability times 1 minus
the predicted probability.
Studentized Residual. The change in the model deviance if a case is excluded.
Standardized Residuals. The residual divided by an estimate of its standard
deviation.
Standardized residuals which are also known as Pearson residuals,
have a mean of 0 and a standard deviation of 1.
Deviance. Residuals based on the model deviance.
Export mode
l information to XML file.
covariances are exported to the specified file in XML (PMML) format. SmartScore
and the server version of SPSS (a separate product) can use this model file to apply
the model i
nformation to other data files for scoring purposes.
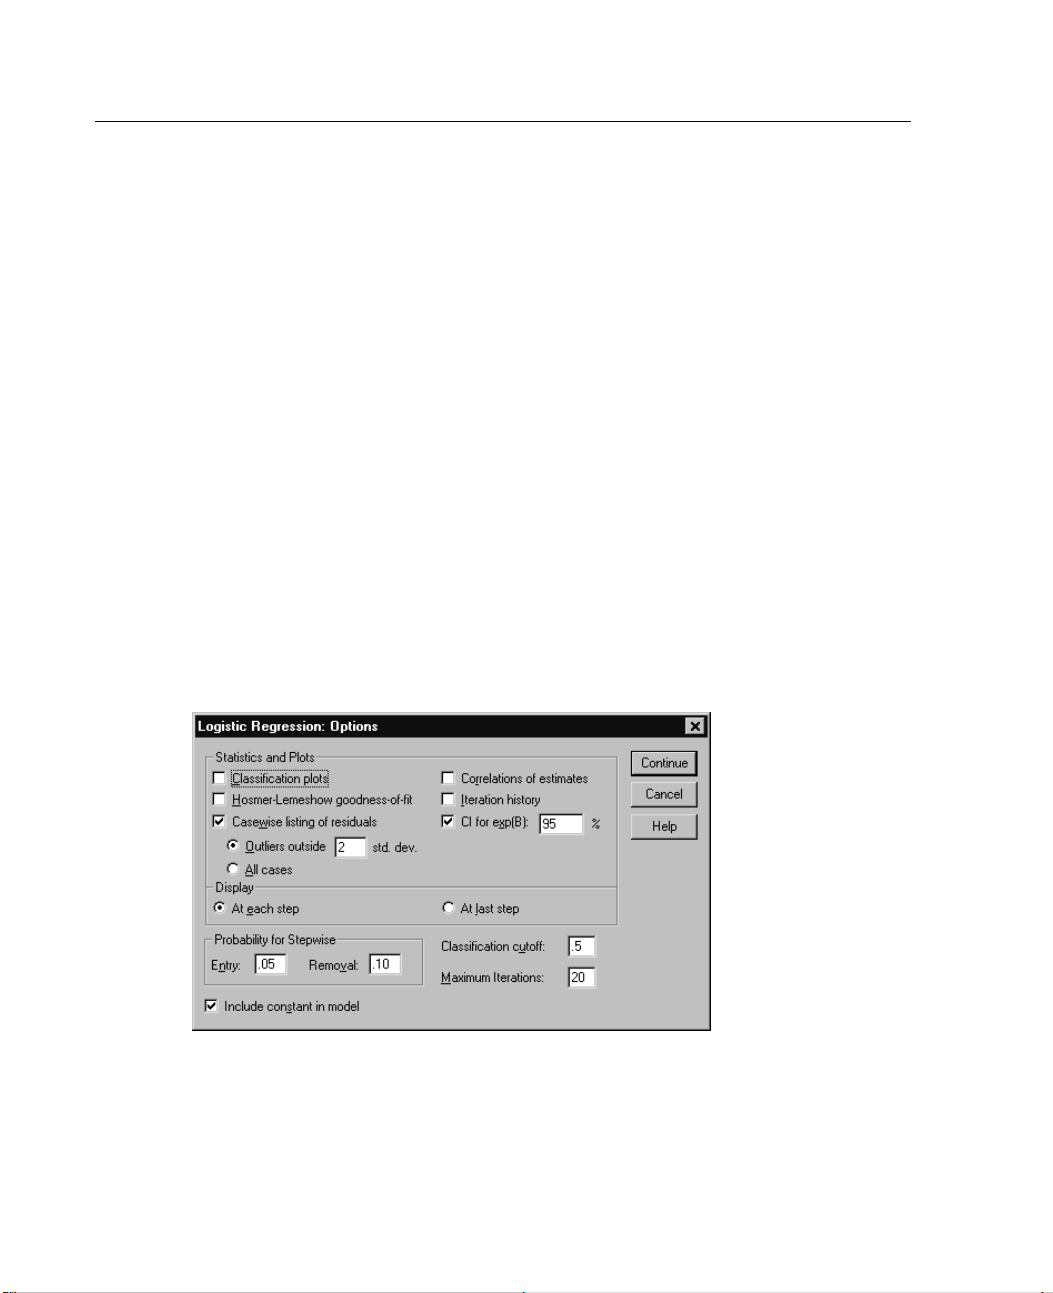
Logistic Regression Options
Figure 2-5
Logistic Regression Options dialog box
Parameter estimates and (optionally) their
Page 21
11
Logistic Regre
ssion
You can specify options for your logistic regression analysis:
Statistics and Plots. Allows you to request statistics and plots. Available options
are Classif
ication plots, Hosmer-Lemeshow goodness-of-fit, Casewise listing of
residuals, Correlations of estimates, Iteration history, and CI for exp(B). Select one of
the alternatives in the Display group to display statistics and plots either At each step
or, only for
Hosmer-Le
the final model, At last step.
meshow goodness-of-fit statistic.
This goodness-of-fit statistic is more
robust than the traditional goodness-of-fit statistic used in logistic regression,
particularly for models with continuous covariates and studies with small sample
sizes. It i
s based on grouping cases into deciles of risk and comparing the
observed probability with the expected probability within each decile.
Probabili
ty for Stepwise.
Allows you to control the criteria by which variables are
entered into and removed from the equation. You can specify criteria for Entry or
Removal of variables.
Probability for Stepwise. A variable is entered into the model if the probability of
its score statistic is less than the Entry value, and is removed if the probability is
greater t
han the Removal value. To override the default settings, enter positive
values for Entry and Removal. Entry must be less than Removal.
Classifi
cation cutoff.
Allows you to determine the cut point for classifying cases.
Cases with predicted values that exceed the classification cutoff are classified as
positive, while those with predicted values smaller than the cutoff are classified as
negativ
e. To change the default, enter a value between 0.01 and 0.99.
LOGIST
Maximum Iterations. Allows you to change the maximum number of times that the
model iterates before terminating.
Include
constant in model.
Allows you to indicate whether the model should include a
constant term. If disabled, the constant term will equal 0.
IC REGRESSION Com mand Additional Features
The SPS
Ident
Contr
S command language also allows you to:
ify casewise output by the values or variable labels of a variable.
ol the spacing of iteration reports. Rather than printing parameter estimates
after every iteration, you can request parameter estimates after everynth iteration.
Page 22
12
Chapter 2
Change the criteria for terminating iteration and checking for redundancy.
Specify a variable list for casewise listings.
Conserve memory by holding the data for each split file group in an external
scratch file
during processing.
See the SPSS Command Syntax Reference for complete syntax information.
Page 23
Chapter
3
Multinomial
Multinomial Logistic Regression is useful for situations in which you want to be
able to clas
of regression is similar to logistic regression, but it is more general because the
dependent variable is not restricted to two categories.
Example. I
what type of film a moviegoer is likely to see. By performing a Multinomial Logistic
Regression, the studio can determine the strength of influence a person’s age, gender,
and datin
advertising campaign of a particular movie towarda group of people likely to go see it.
Statistics. Iteration history, parameter coefficients, asymptotic covariance and
correlat
log-likelihood. Pearson and deviance chi-square goodness of fit. Cox and Snell,
Nagelkerke, and McFadden R
by respo
residuals) and proportions by covariate pattern and response category.
sify subjects based on values of a set of predictor variables. This type
n order to market films more effectively, movie studios want to predict
g status has upon the type of film they prefer. The studio can then slant the
ion matrices, likelihood-ratio tests for model and partial effects, –2
nse category. Crosstabulation: observed and predicted frequencies (with
Logistic Regression
2
. Classification: observed versus predicted frequencies
Methods. A multinomial logit model is fit for the full factorial model or a
user-sp
maximum-likelihood algorithm.
Data. The dependent variable should be categorical. Independent variables can be
factor
should be continuous variables.
Assumptions. It is assumed that the odds ratio of any two categories are independent
of all o
market, this assumption states that the market shares of all other products are affected
proportionally equally. Also, given a covariate pattern, the responses are assumed to
be ind
ecified model. Parameter estimation is performed through an iterative
s or covariates. In general, factors should be categorical variables and covariates
ther response categories. For example, if a new product is introduced to a
ependent multinomial variables.
13
Page 24
14
Chapter 3
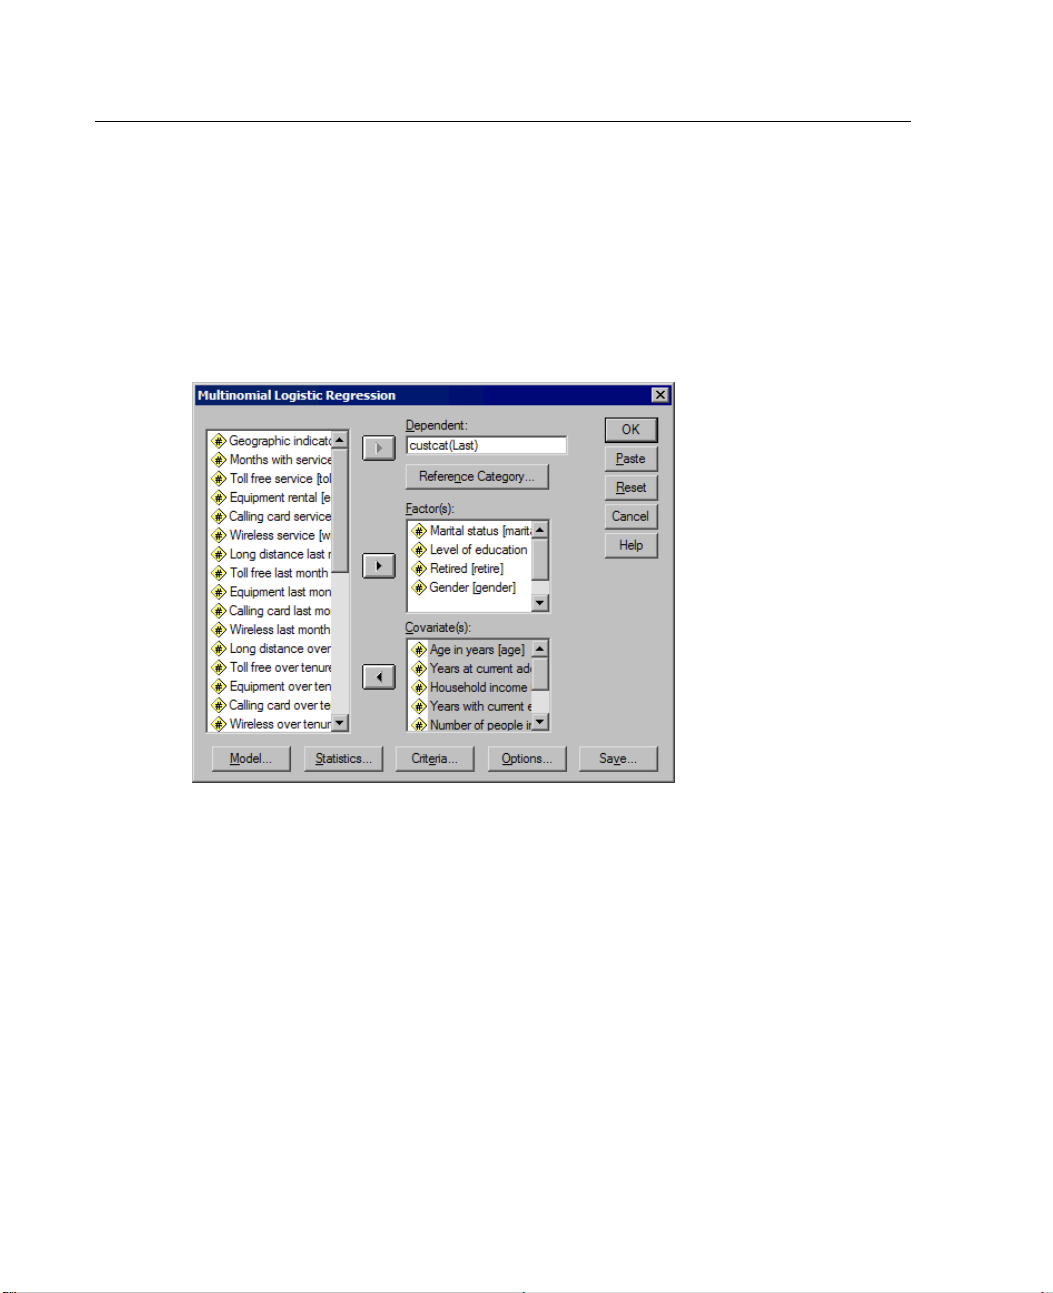
Obtaining a Multinomial Lo gistic Regression
E From the menus choose:
Analyze
Regression
Multinomial Logistic...
Figure 3-1
Multinomial Logistic Regression dialog box
E Select
E Factor
E Covari
one dependent variable.
s are optional and can be either numeric or categorical.
ates are optional but must be numeric if specified.
Page 25
15
Multinomial
Figure 3-2
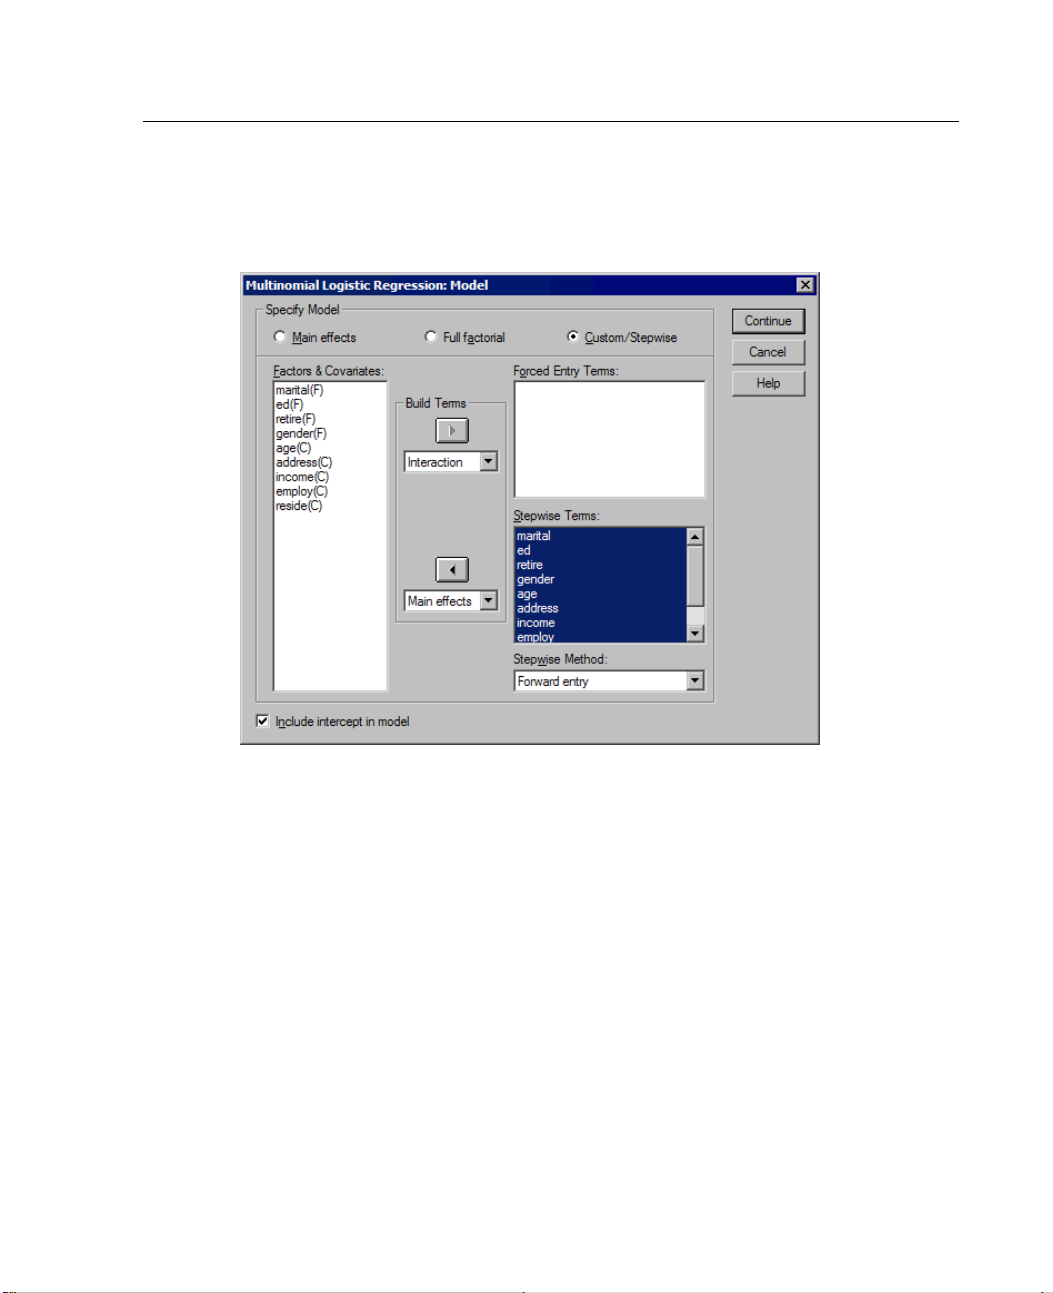
Multinomial Logistic Regression Mod el dialog box
Logistic Regression Models
Multinomial Lo
gistic Regression
By default, the Multinomial Logistic Regression procedure produces a model with
the factor and covariate main effects, but you can specify a custom model or request
stepwise model selection with this dialog box.
Specify M odel. A main-effects model contains the covariate and factor main effects
but no interaction effects. A full factorial model contains all main effects and all
factor-by-factor interactions. It does not contain covariateinteractions. You can create
a custom model to specify subsets of factor interactions or covariate interactions, or
request stepwise selection of model terms.
Factors and Covariates. The factors and covariates are listed with (F) for factor and
(C) for covariate.
Forced Entry Terms. Terms added to the forced entry list are always included in the
model.
Page 26
16
Chapter 3
Stepwise Terms. Terms added to the stepwise list are included in the model according
to one of the following user-selected methods:
Forward entry. This method begins with no stepwise terms in the model. At each
step, the most significant term is added to the model until none of the stepwise
terms left o
ut of the model would have a statistically significant contribution if
addedtothemodel.
Backward elimination. This method begins by entering all terms specified on the
stepwise list into the model. At each step, the least significant stepwise term
is removed
from the model until all of the remaining stepwise terms have a
statistically significant contribution to the model.
Forward s tepwise. This method begins with the model that would be selected by
the forward entry method. From there, the algorithm alternates between backward
eliminati
on on the stepwise terms in the model and forward entry on the terms left
out of the model. This continues until no terms meet the entry or removal criteria.
Backward stepwise. This method begins with the model that would be selected by
the backward elimination method. From there, the algorithm alternates between
forward e
ntry on the terms left out of the model and backward elimination on
the stepwise terms in the model. This continues until no terms meet the entry or
removal criteria.
Include intercept in model. Allows you to include or exclude an intercept term for the
model.
Build Terms
For the selected factors and covariates:
Interac
Main effects. Creates a main-effects term for each variable selected.
All 2-way. Creates all possible two-way interactions of the selected variables.
All 3-wa
All 4-way. Creates all possible four-way interactions of the selected variables.
All 5-way. Creates all possible five-way interactions of the selected variables.
tion.
Creates the highest-level interaction term of all selected variables.
y.
Creates all possible three-way interactions of the selected variables.
Page 27
17
Multinomial
Figure 3-3
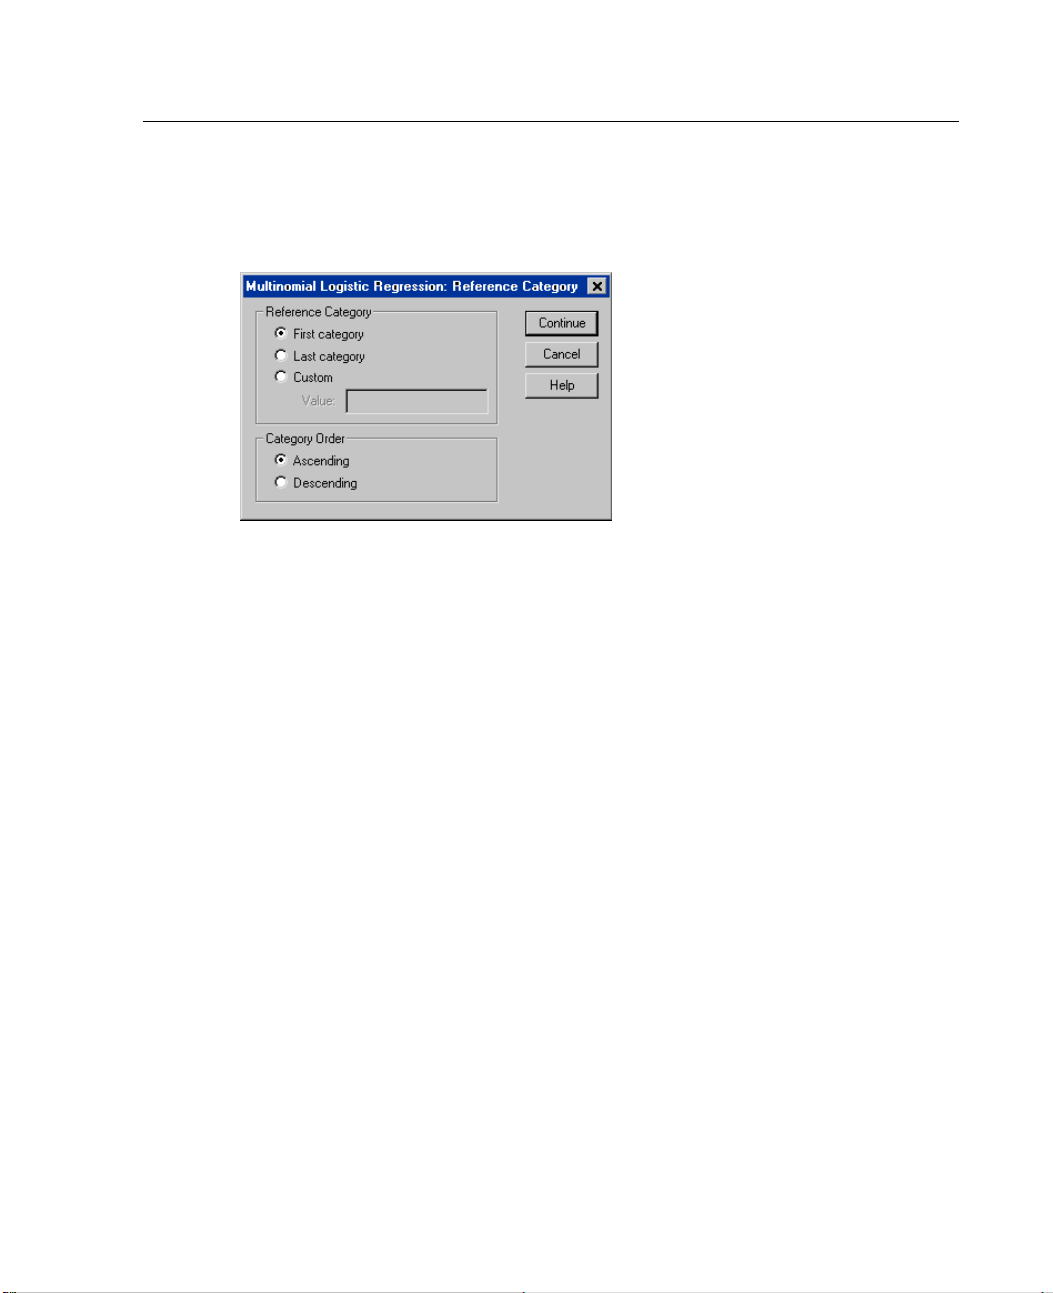
Multinomial Logistic Regression Reference Category dialog box
By default, the Multinomial Logistic Regression procedure makes the last category
the reference category. This dialog box gives you control of the reference category
and the w
Reference Categ ory. Specify the first, last, or a custom category.
Category Order. In ascending order, the lowest value defines the first category and the
highest
category and the lowest value defines the last.
Multinomial Lo
gistic Regression
Logistic Regression Reference Category
ay in which categories are ordered.
value defines the last. In descending order, the highest value defines the first
Page 28
18
Chapter 3
Multinomial
Figure 3-4
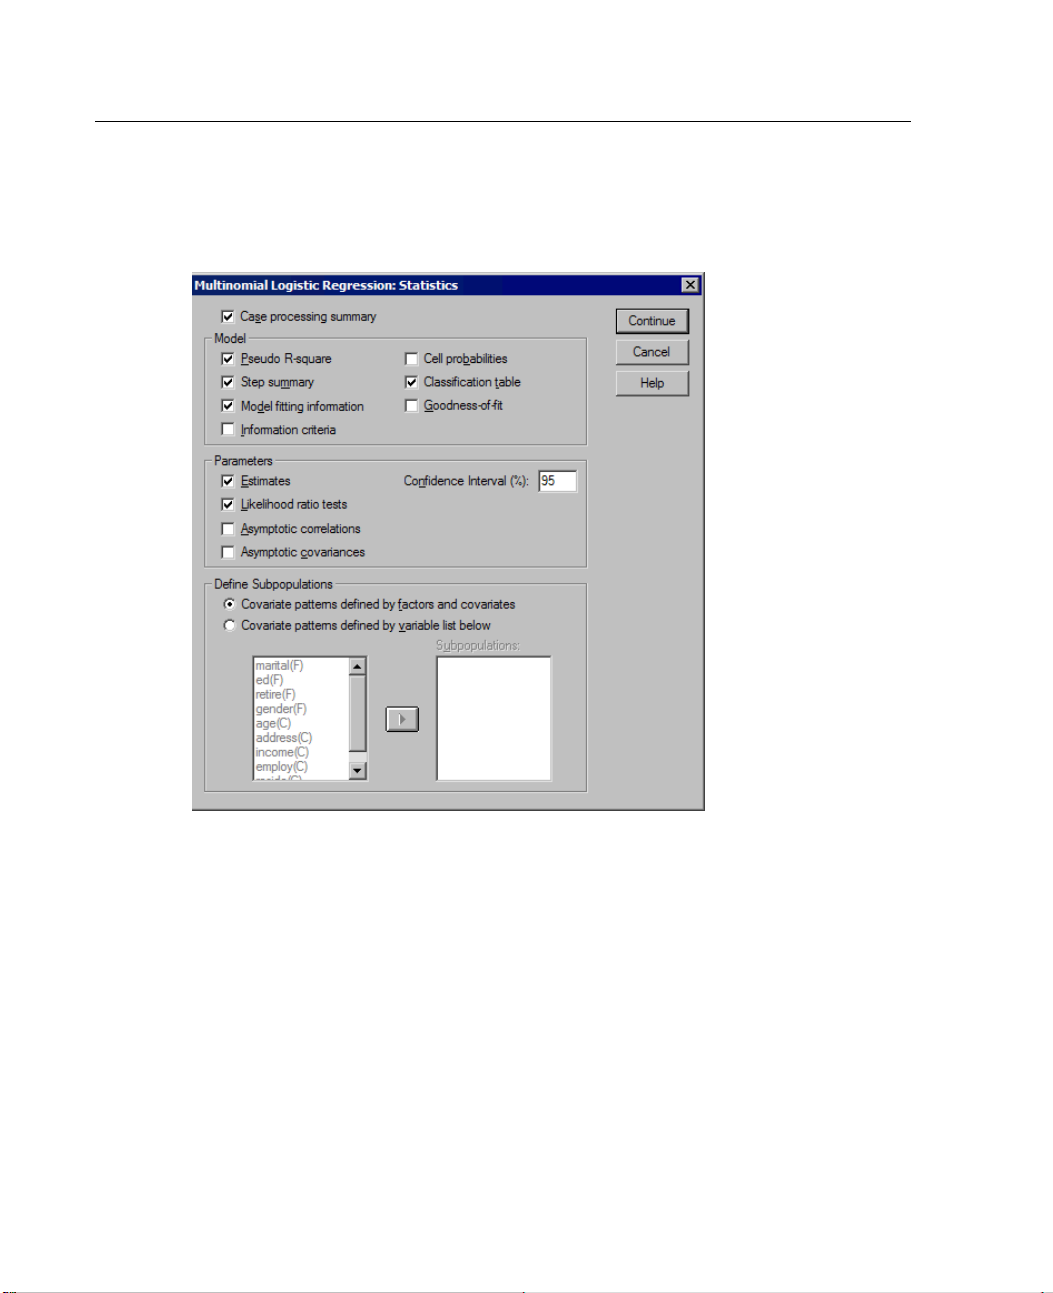
Multinomial Logistic Regression Statistics dialog box
Logistic Regression Statistics
You can specify the following statistics for your Multinomial Logistic Regression:
Case processing summary. This table contains information about the specified
categorical variables.
Model. Statistics for the overall model.
Summary statistics. Prints the Cox and Snell, Nagelkerke, and McFadden R
2
statistics.
Step summary. This table summarizes the effects entered or removed at each step
in a stepwise method. It is not produced unless a stepwise model is specified in
the Model dialog box.
Page 29
19
Multinomial Lo
Model fitting information. This table compares the fitted and intercept-only
or null mode
Informatio
ls.
n criteria.
This table prints Akaike’s information criterion (AIC) and
gistic Regression
Schwarz’s Bayesian information criterion (BIC).
Cell probabilities. Prints a table of the observed and expected frequencies (with
residual) and proportions by covariate pattern and response category.
Classification table. Prints a table of the observed versus predicted responses.
Goodness of fit chi-square statistics. Prints Pearson and likelihood-ratio chi-square
statistics
. Statistics are computed for the covariate patterns determined by all
factors and covariates or by a user-defined subset of the factors and covariates.
.
Parameters
Estimates
Statistics related to the model parameters.
.
Prints estimates of the model parameters, with a user-specified level of
confidence.
Likelihood ratio test. Prints likelihood-ratio tests for the model partial effects. The
test for the overall model is printed automatically.
Asymptotic correlations. Prints matrix of parameter estimate correlations.
Asymptotic covarianc es. Prints matrix of parameter estimate covariances.
Define Sub populations. Allows you to select a subset of the factors and covariates in
order to define the covariate patterns used by cell probabilities and the goodness-of-fit
tests.
Page 30
20
Chapter 3
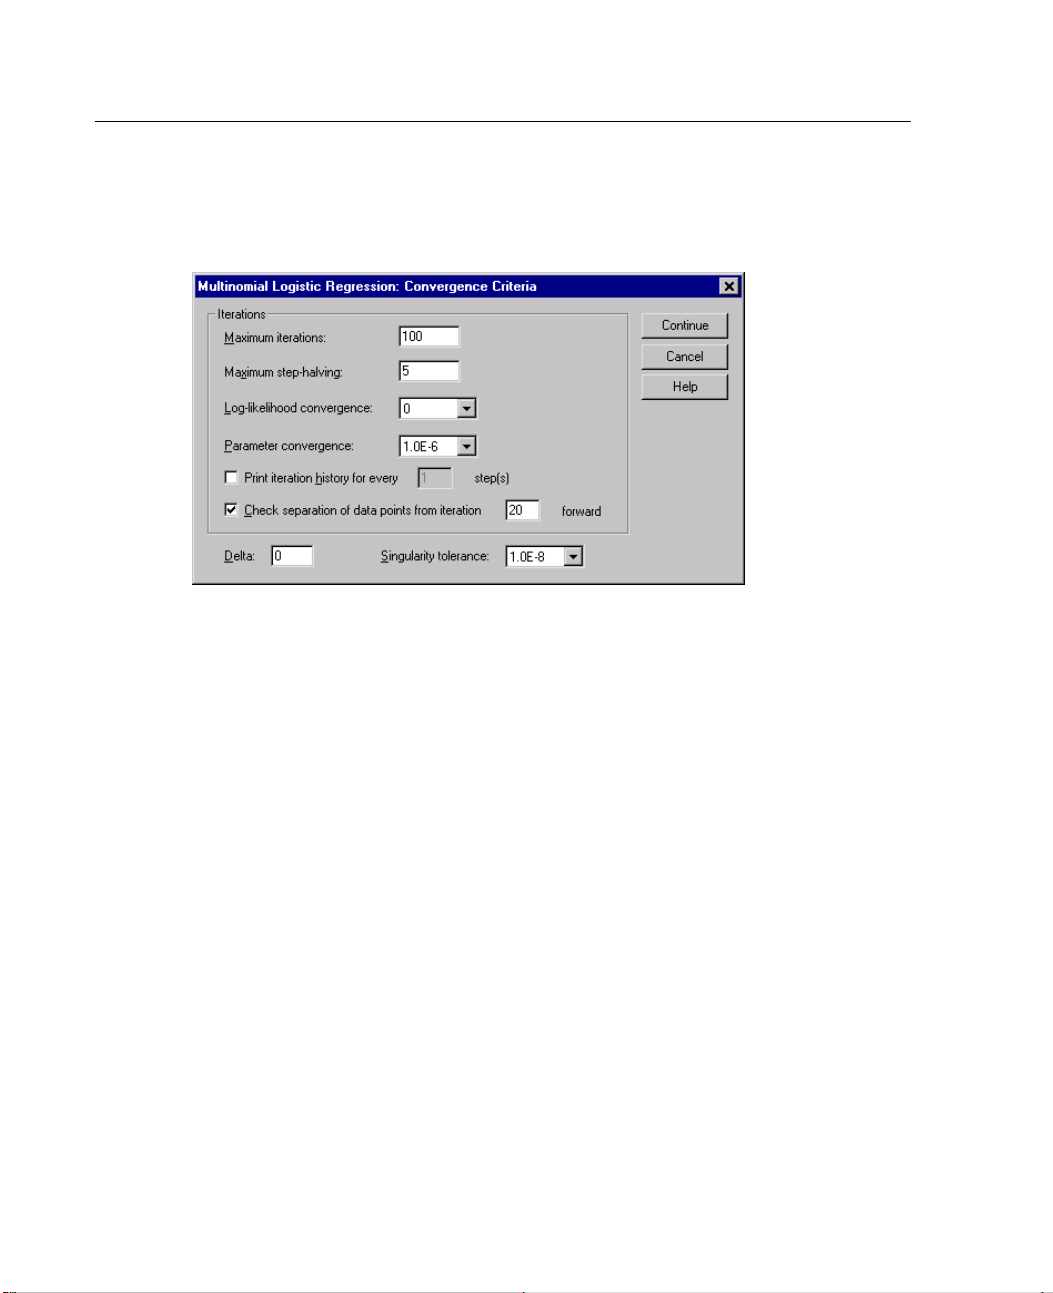
Multinomial
Figure 3-5
Multinomial Logistic Regression Convergence Criteria dialog box
You can specify the following criteria for your Multinomial Logistic Regression:
Iterations. Allows you to specify the maximum number of times you want to cycle
through the algorithm, the maximum number of steps in the step-halving, the
convergence tolerances for changes in the log-likelihood and parameters, how often
the progress of the iterative algorithm is printed, and at what iteration the procedure
should begin checking for complete or quasi-complete separation of the data.
Log-likelihood convergence. Convergence is assumed if the absolute change in
the log-likelihood function is less than the specified value. The criterion is not
used if the value is 0. Specify a non-negative value.
Parameter con vergence. Convergence is assumed if the absolute change in the
parameter estimates is less than this value. The criterion is not used if the
value is 0.
Logistic Regression Criteria
Delta. Allows you to specify a non-negative value less than 1. This value is added to
each empty cell of the crosstabulation of response category by covariate pattern. This
helps to stabilize the algorithm and prevent bias in the estimates.
Singularity tolerance. Allows you to specify the tolerance used in checking for
singularities.
Page 31
21
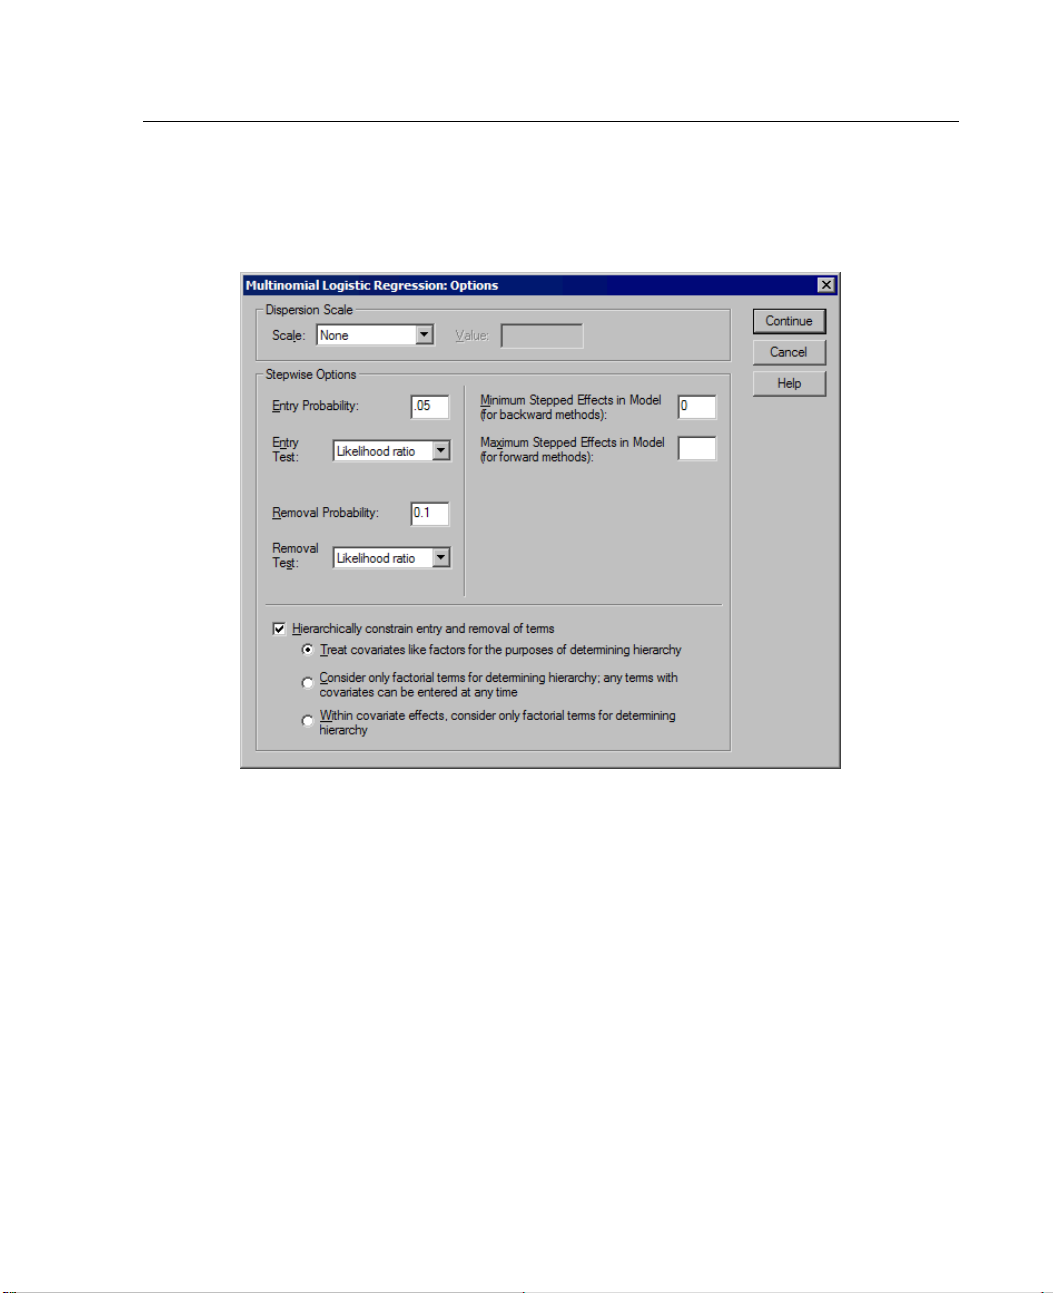
Multinomial
Figure 3-6
Multinomial Logistic Regression Options dialog box
Logistic Regression Options
Multinomial Lo
gistic Regression
You can
Dispersion Scale. Allows you to specify the dispersion scaling value that will be
specify the following options for your Multinomial Logistic Regression:
used to correct the estimate of the parameter covariance matrix. Deviance estimates
aling value using the deviance function (likelihood-ratio chi-square) statistic.
the sc
Pearson estimates the scaling value using the Pearson chi-square statistic. You can
also specify your own scaling value. It must be a positive numeric value.
Stepw
ise Options.
These options give you control of the statistical criteria when
stepwise methods are used to build a model. They are ignored unless a stepwise
model is specified in the Model dialog box.
Page 32
22
Chapter 3
Entry Probability. This is the probability of the likelihood-ratio statistic for variable
entry. The l
arger the specified probability, the easier it is for a variable to enter
the model. This criterion is ignored unless the forward entry, forward stepwise,
or backward stepwise method is selected.
Entry test. This is the method for entering terms in stepwise methods. Choose
between the
likelihood-ratio test and score test. This criterion is ignored unless
the forward entry, forward stepwise, or backward stepwise method is selected.
Removal Probability. This is the probability of the likelihood-ratio statistic for
variable removal. The larger the specified probability, the easier it is for a variable
to remain i
n the model. This criterion is ignored unless the backward elimination,
forward stepwise, or backward stepwise method is selected.
Removal test. This is the method for removing terms in stepwise methods. Choose
between the likelihood-ratio test and Wald test. This criterion is ignored unless
the backw
ard elimination, forward stepwise, or backward stepwise method
is selected.
Minimum Stepped Effect in Model. When using the backward elimination or
backward stepwise methods, this specifies the minimum number of terms to
include i
Maximum
n the model. The intercept is not counted as a model term.
Stepped Effect in Model.
When using the forward entry or forward
stepwise methods, this specifies the maximum number of terms to include in the
model. The intercept is not counted as a model term.
Hierarchically constrain entry and removal of terms. This option allows you to
choose w
hether to place restrictions on the inclusion of model terms. Hierarchy
requires that for any term to be included, all lower order terms that are a part of
the term to be included must be in the model first. For example, if the hierarchy
ment is in effect, the factors Marital status and Gender must both be in the
require
model before the Marital Status*Gender interaction can be added. The three
radio button options determine the role of covariates in determining hierarchy.
Page 33
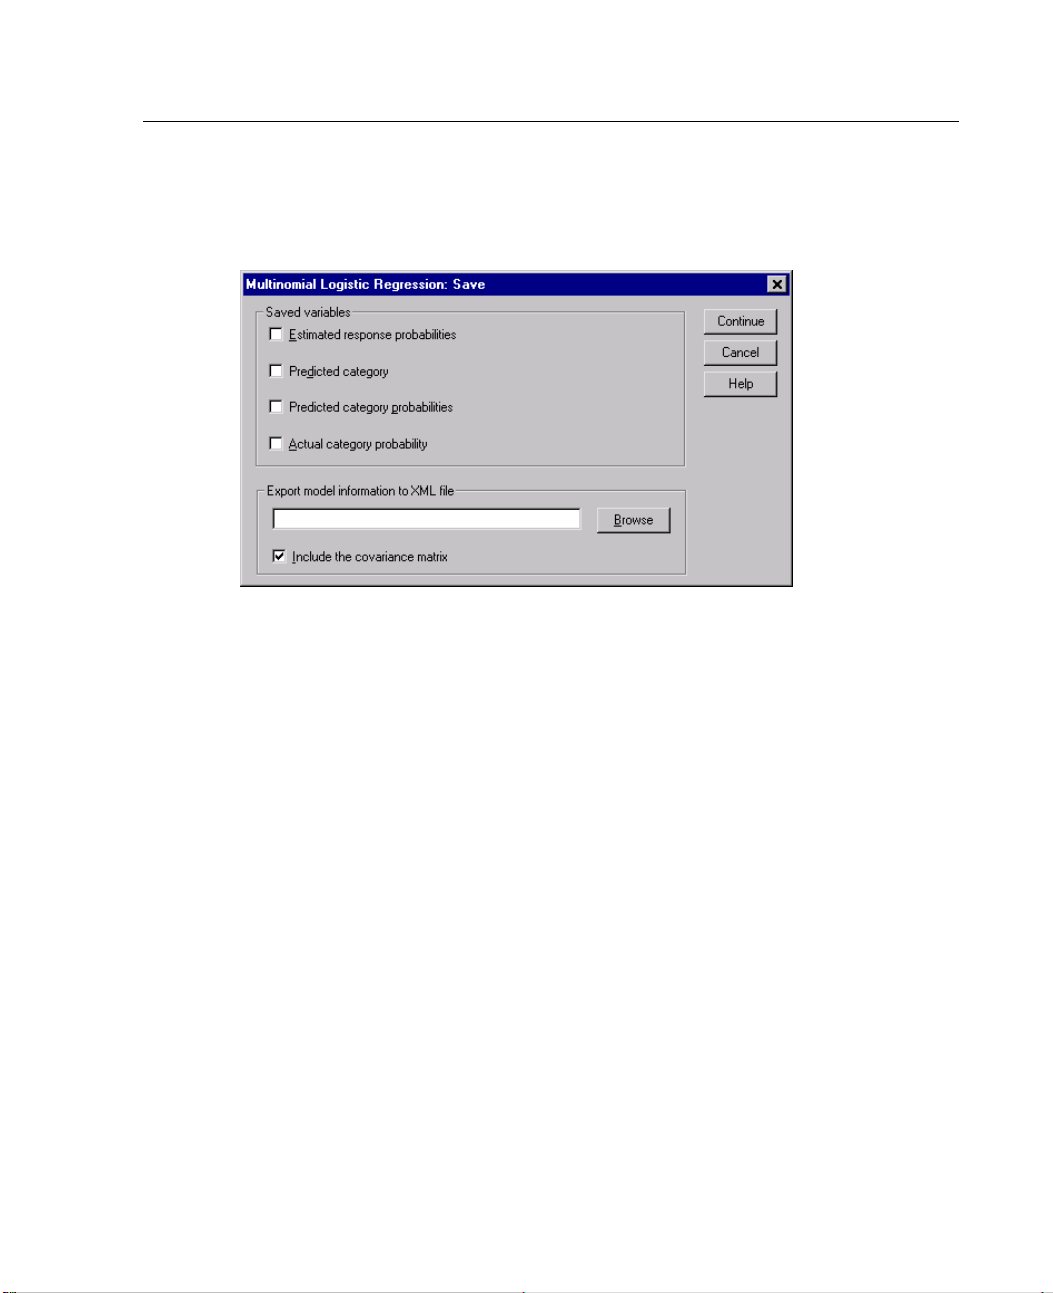
23
Multinomial
Figure 3-7
Multinomial Logistic Regression Save dialog box
The Save dialog box allows you to save variables to the working file and export
model information to an external file.
Saved va
Estima
classifying a factor/covariate pattern into the response categories. There are as
many estimated probabilities as there are categories of the response variable; up
to 25 wil
Predic
probability for a factor/covariate pattern.
Predicted category probabilities. This is the maximum of the estimated response
probabilities.
Actual category probability. This is the estimated probability of classifying a
factor
Logistic Regression Save
riables:
ted response probabilities.
lbesaved.
ted category.
This is the response category with the largest expected
/covariate pattern into the observed category.
These are the estimated probabilities of
Multinomial Lo
gistic Regression
model information to XML file.
Export
Parameter estimates and (optionally) their
covariances are exported to the specified file in XML (PMML) format. SmartScore
and the server version of SPSS (a separate product) can use this model file to apply
the mod
el information to other data files for scoring purposes.
Page 34
24
Chapter 3
NOMREG Comma
The SPSS com
Specify the
Include cas
Customize h
of parameters.
See the SPSS
nd Additional Features
mand language also allows you to:
reference category of the dependent variable.
es with user-missing values.
ypothesis tests by specifying null hypotheses as linear combinations
Command Syntax Reference for complete syntax information.
Page 35
Chapter
4
Probit Analy
This procedure measures the relationship between the strength of a stimulus and the
proportion
situations where you have a dichotomous output that is thought to be influenced or
caused by levels of some independent variable(s) and is particularly well suited to
experimen
required to induce a certain proportion of responses, such as the median effective dose.
Example. How effective is a new pesticide at killing ants, and what is an appropriate
concentr
of ants to different concentrations of the pesticide and then record the number of ants
killed and the number of ants exposed. Applying probit analysis to these data, you
can deter
you can determine what the appropriate concentration of pesticide would be if you
wanted to be sure to kill, say, 95% of exposed ants.
Statist
error, Pearson goodness-of-fit chi-square, observed and expected frequencies, and
confidence intervals for effective levels of independent variable(s). Plots: transformed
respon
of cases exhibiting a certain response to the stimulus. It is useful for
tal data. This procedure will allow you to estimate the strength of a stimulus
ation to use? You might perform an experiment in which you expose samples
mine the strength of the relationship between concentration and killing, and
ics.
Regression coefficients and standard errors, intercept and standard
se plots.
sis
®
This pr
Murray, Saunders & Wright to estimate the model parameters.
Data. For each value of the independent variable (or each combination of values for
multip
number of cases with those values that show the response of interest, and the total
observed variable should be a count of the total number of cases with those values for
the in
ocedure uses the algorithms proposed and implemented in NPSOL
le independent variables), your response variable should be a count of the
dependent variable. The factor variable should be categorical, coded as integers.
25
by Gill,
Page 36
26
Chapter 4
Assumptions. Observations should be independent. If you have a large number of
values for the independent variables relative to the number of observations, as you
mightinano
bservational study, the chi-square and goodness-of-fit statistics may
not be valid.
Related procedures. Probit analysis is closely related to logistic regression; in fact, if
you choose t
he logit transformation, this procedure will essentially compute a logistic
regression. In general, probit analysis is appropriate for designed experiments,
whereas logistic regression is more appropriate for observational studies. The
differenc
es in output reflect these different emphases. The probit analysis procedure
reports estimates of effective values for various rates of response (including median
effective dose), while the logistic regression procedure reports estimates of odds
ratios fo
r independent variables.
Obtaining a Probit Analysis
E From the menus choose:
Analyze
Regressi
Probit..
on
.
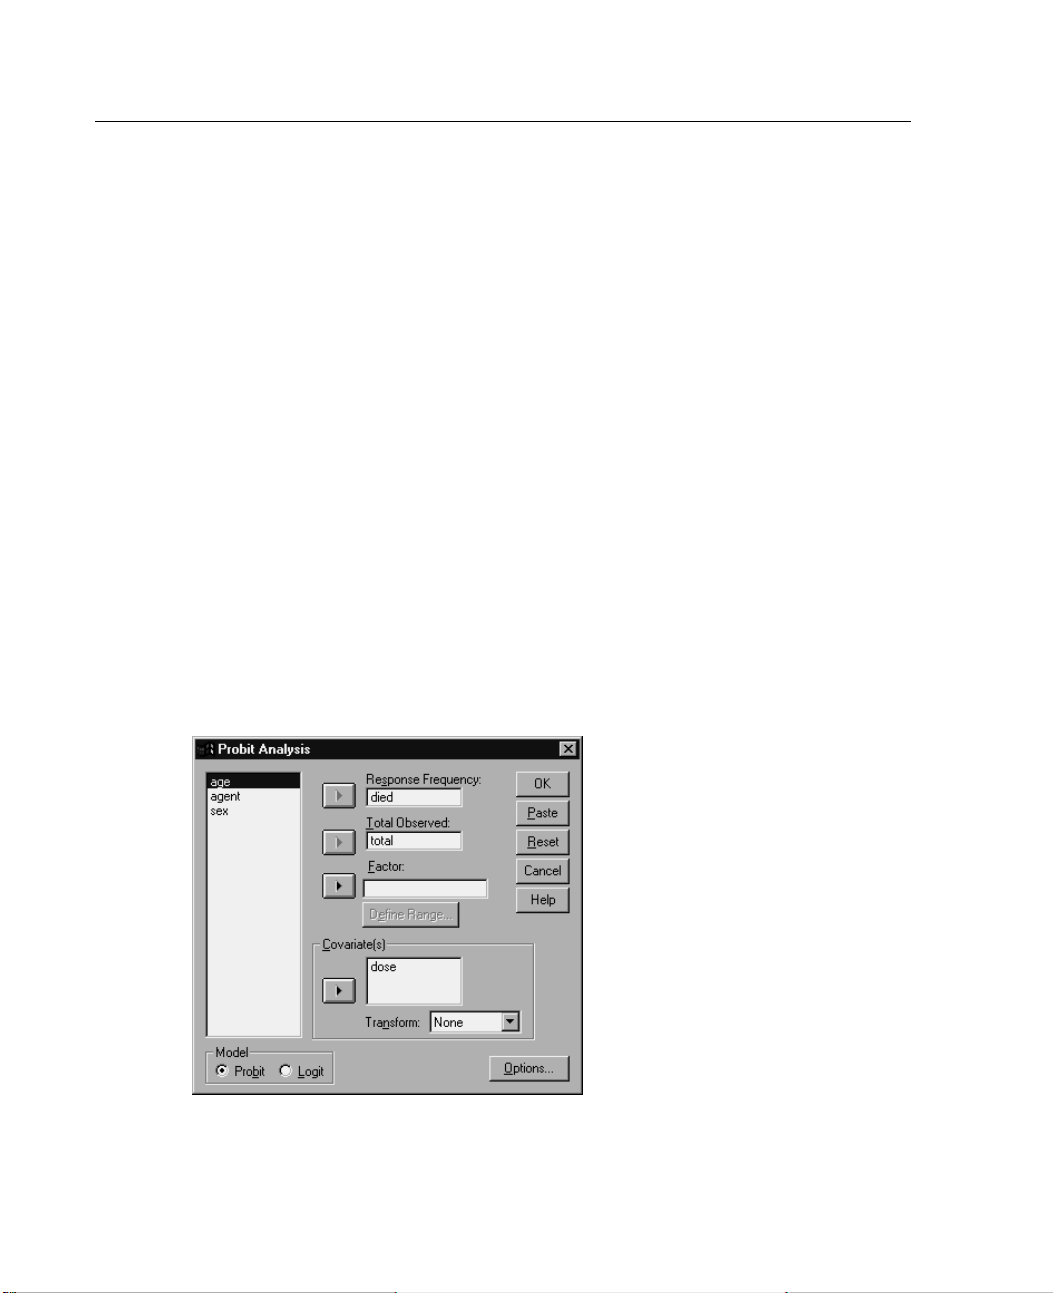
Figure 4-1
Probit Analysis dialog box
Page 37
27
Probit Analysi
E
Select a response frequency variable. This variable indicates the number of cases
exhibiting a response to the test stimulus. The values of this variable cannot be
negative.
E Select a to
tal observed variable. This variable indicates the number of cases to which
the stimulus was applied. The values of this variable cannot be negative and cannot
be less than the values of the response frequency variable for each case.
Optionally, you can select a Factor variable. If you do, click
Define Range to define
the groups.
E Select one or more covariate(s). This variable contains the level of the stimulus
applied to
each observation. If you want to transform the covariate, select a
transformation from the Transform drop-down list. If no transformation is applied
and there is a control group, then the control group is included in the analysis.
E Select either the Probit or Logit model.
Probit Model. Applies the probit transformation (the inverse of the cumulative
standard normal distribution function) to the response proportions.
Logit Model. Applies the logit (log odds) transformation to the response
proporti
ons.
s
Probit Analysis Define Range
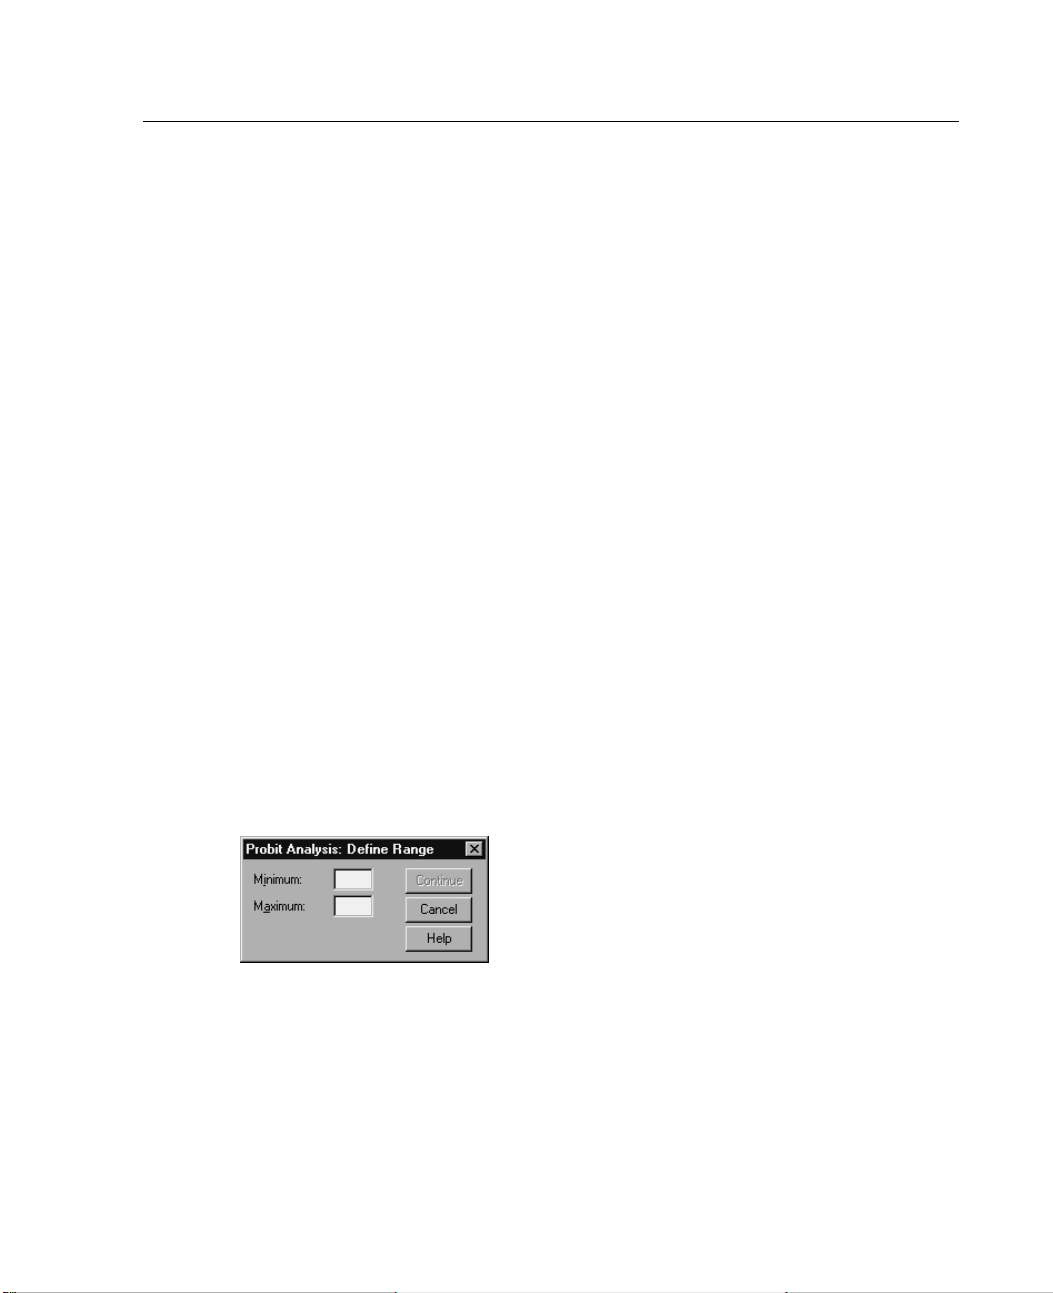
Figure 4-2
Probit Analysis Define Range dialog box
This allows you to specify the levels of the factor variable that will be analyzed. The
factor levels must be coded as consecutive integers, and all levels in the range that
you spe
cify will be analyzed.
Page 38
28
Chapter 4
Probit A naly
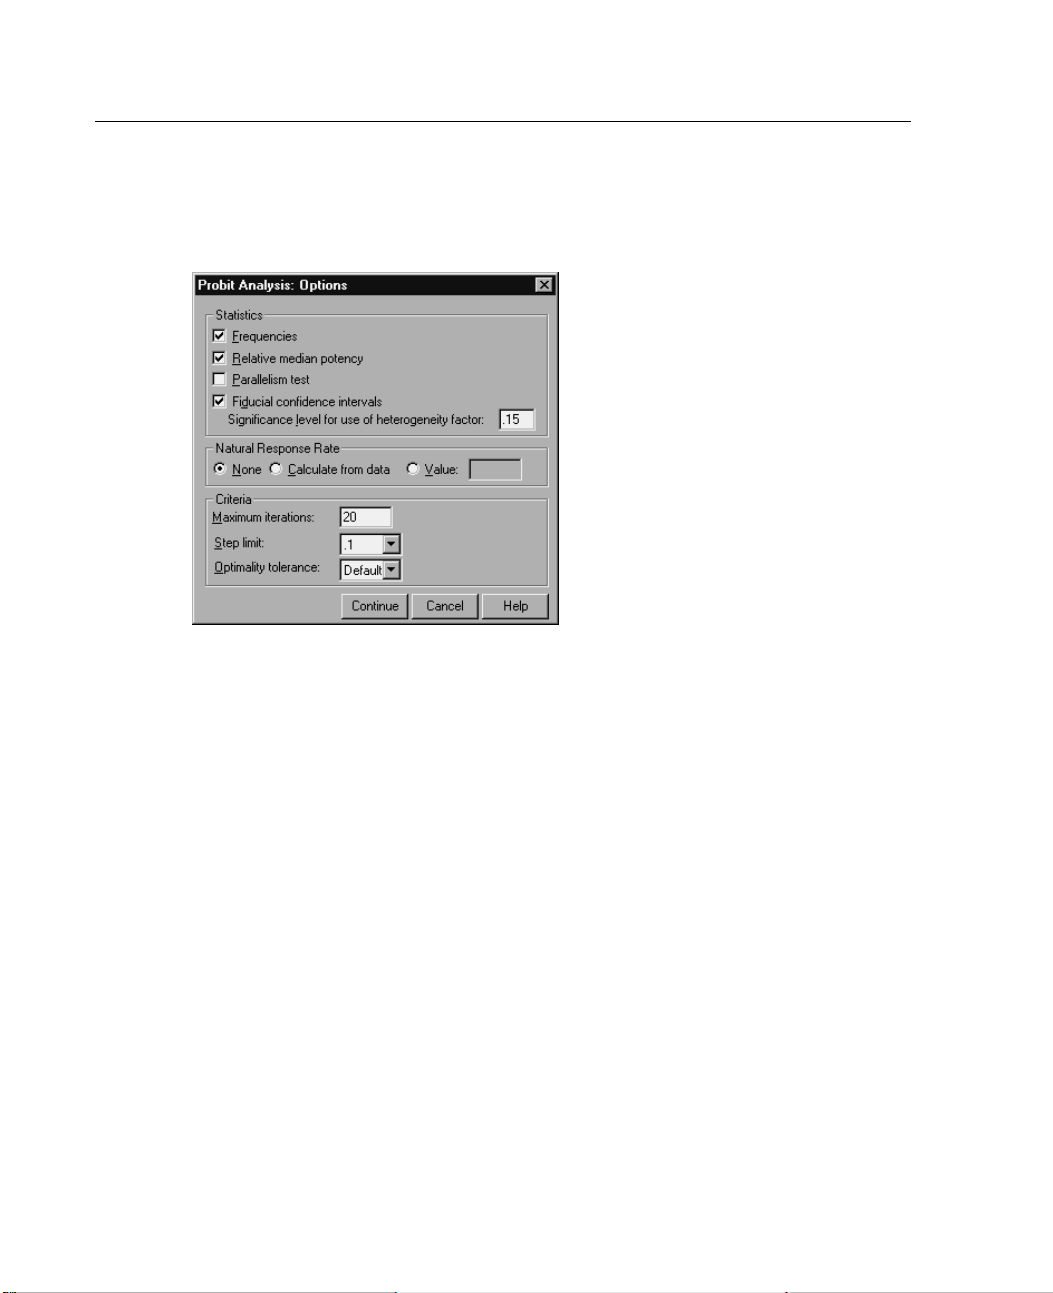
Figure 4-3
Probit Analysis Options dialog box
You can specify options for your probit analysis:
Statistics. Allows you to request the following optional statistics: Frequencies,
Relative median potency, Parallelism test, and Fiducial confidence intervals.
Relative Median Potency. Displays the ratio of median potencies for each pair
of factor levels. Also shows 95% confidence limits for each relative median
potency. Relative median potencies are not available if you do not have a factor
variable or if you have more than one covariate.
Parallelism Test. A test of the hypothesis that all factor levels have a common
slope.
Fiducial Confidence Intervals. Confidence intervals for the dosage of agent
required to produce a certain probability of response.
sis Options
Fiducial confidence intervals and Relative median potency are unavailable if you have
selected more than one covariate. Relative median potency and Parallelism test are
available only if you have selected a factor variable.
Natural Response Rate. Allows you to indicate a natural response rate even in the
absence of the stimulus. Available alternatives are None, Calculate from data,
or Value.
Page 39
29
Value. Sets the natural response rate in the model (select this item when you know
Criteria. Allows you to control parameters of the iterative parameter-estimation
algorithm
Optimality tolerance.
PROBIT Co
The SPSS c
Request a
Control t
Transfor
Probit Analysi
Calculate from Data. Estimate the natural response rate from the sample data. Your
data should
contain a case representing the control level, for which the value
of the covariate(s) is 0. Probit estimates the natural response rate using the
proportion of responses for the control level as an initial value.
the natural
response rate in advance). Enter the natural response proportion (the
proportion must be less than 1). For example, if the response occurs 10% of the
time when the stimulus is 0, enter 0.10.
. You can override the defaults for Maximum iterations, Step limit, and
mmand Additional Features
ommand language also allows you to:
n analysis on both the probit and logit models.
he treatment of missing values.
m the covariates by bases other than base 10 or natural log.
s
See the SPSS Command Syntax Reference for complete syntax information.
Page 40
Page 41
Chapter
5
Nonlinear Re
Nonlinear regression is a method of finding a nonlinear model of the relationship
between the
linear regression, which is restricted to estimating linear models, nonlinear regression
can estimate models with arbitrary relationships between independent and dependent
variables
procedure is not necessary for simple polynomial models of the form Y = A + BX**2.
By defining W = X**2, we get a simple linear model, Y = A + BW, which can be
estimate
Example. Can population be predicted based on time? A scatterplot shows that there
seems to be a strong relationship between population and time, but the relationship is
nonlinea
procedure. By setting up an appropriate equation, such as a logistic population growth
model, we can get a good estimate of the model, allowing us to make predictions
about po
Statistics. For each iteration: parameter estimates and residual sum of squares. For
each model: sum of squares for regression, residual, uncorrected total and corrected
total,
matrix of parameter estimates.
dependent variable and a set of independent variables. Unlike traditional
. This is accomplished using iterative estimation algorithms. Note that this
d using traditional methods such as the Linear Regression procedure.
r, so it requires the special estimation methods of the Nonlinear Regression
pulation for times that were not actually measured.
parameter estimates, asymptotic standard errors, and asymptotic correlation
gression
Note: Constrained nonlinear regression uses the algorithms proposed and
®
implemented in NPSOL
model p
Data. The dependent and independent variables should be quantitative. Categorical
variables, such as religion, major, or region of residence, need to be recoded to binary
(dumm
arameters.
y) variables or other types of contrast variables.
by Gill, Murray, Saunders, and Wright to estimate the
31
Page 42
32
Chapter 5
Assumptions. Results are valid only if you have specified a function that accurately
describes the relationship between dependent and independent variables.
Additional
ly, the choice of good starting values is very important. Even if you’ve
specified the correct functional form of the model, if you use poor starting values,
your model may fail to converge or you may get a locally optimal solution rather
than one th
at is globally optimal.
Related procedures. Many models that appear nonlinear at first can be transformed to
a linear model, which can be analyzed using the Linear Regression procedure. If you
are uncert
ain what the proper model should be, the Curve Estimation procedure can
help to identify useful functional relations in your data.
Obtaining
E From the
Analyze
Regression
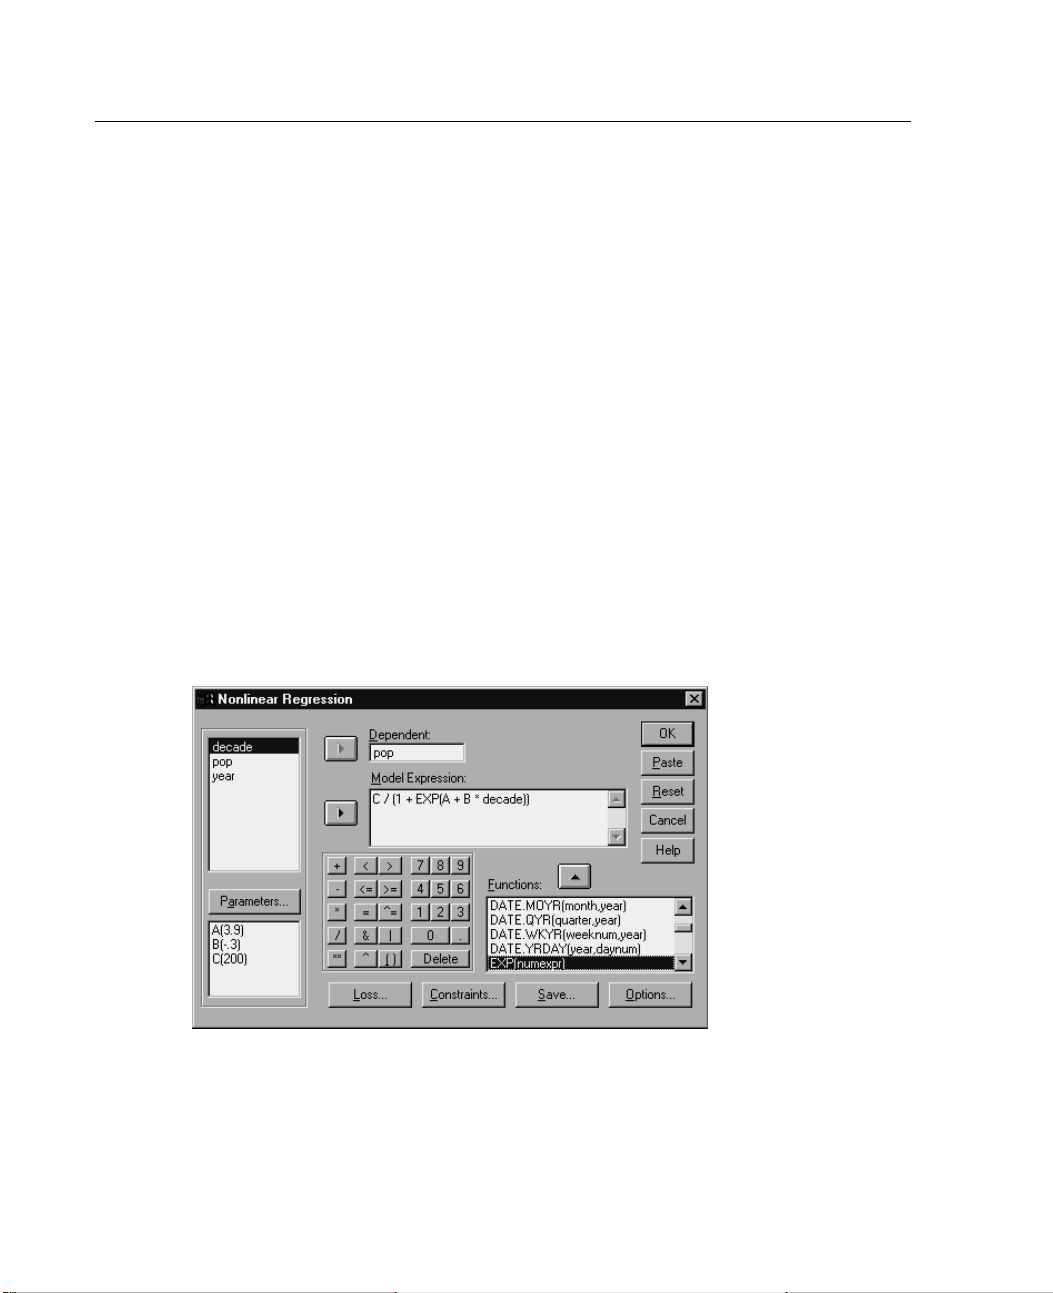
Figure 5-
Nonlinea
E Select one numeric dependent variable from the list of variables in your working
a Nonlinear Regression Analysis
menus choose:
Nonlinear...
1
r Regression dialog box
data file.
Page 43
33
E
To build a model expression, enter the expression in the Model field or paste
components (variables, parameters, functions) into the field.
E Identify parameters in your model by clicking Parameters.
Asegmentedm
must be specified by using conditional logic within the single model statement.
Conditiona
You can spec
within a model expression or a loss function, you form the sum of a series of terms,
one for each condition. Each term consists of a logical expression (in parentheses)
multiplie
For example, consider a segmented model that equals 0 for X<=0, X for 0<X<1, and
1 for X>=1. The expression for this is:
(X<=0)*0 +
The logical expressions in parentheses all evaluate to 1 (true) or 0 (false). Therefore:
If X<=0, the above reduces to 1*0 + 0*X + 0*1=0.
Nonlinear Regr
odel (one that takes different forms in different parts of its domain)
l Logic (Nonlinear Regression)
ify a segmented model using conditional logic. To use conditional logic
d by the expression that should result when that logical expression is true.
(X>0 & X < 1)*X + (X>=1)*1.
ession
If 0<X<1, i
If X>=1, it reduces to 0*0 + 0*X + 1*1 = 1.
More complicated examples can be easily built by substituting different logical
expressio
0<X<1, must be written as compound expressions, such as (X>0 & X < 1).
String variables can be used within logical expressions:
(city=‘Ne
This yields one expression (the value of the variable costliv) for New Yorkers and
another (59% of that value) for Des Moines residents. String constants must be
enclosed
t reduces to 0*0 + 1*X +0*1 = X.
ns and outcome expressions. Remember that double inequalities, such as
w York’)*costliv + (city=‘Des Moines’)*0.59*costliv
in quotation marks or apostrophes, as shown here.
Page 44
34
Chapter 5
Nonlinear Re
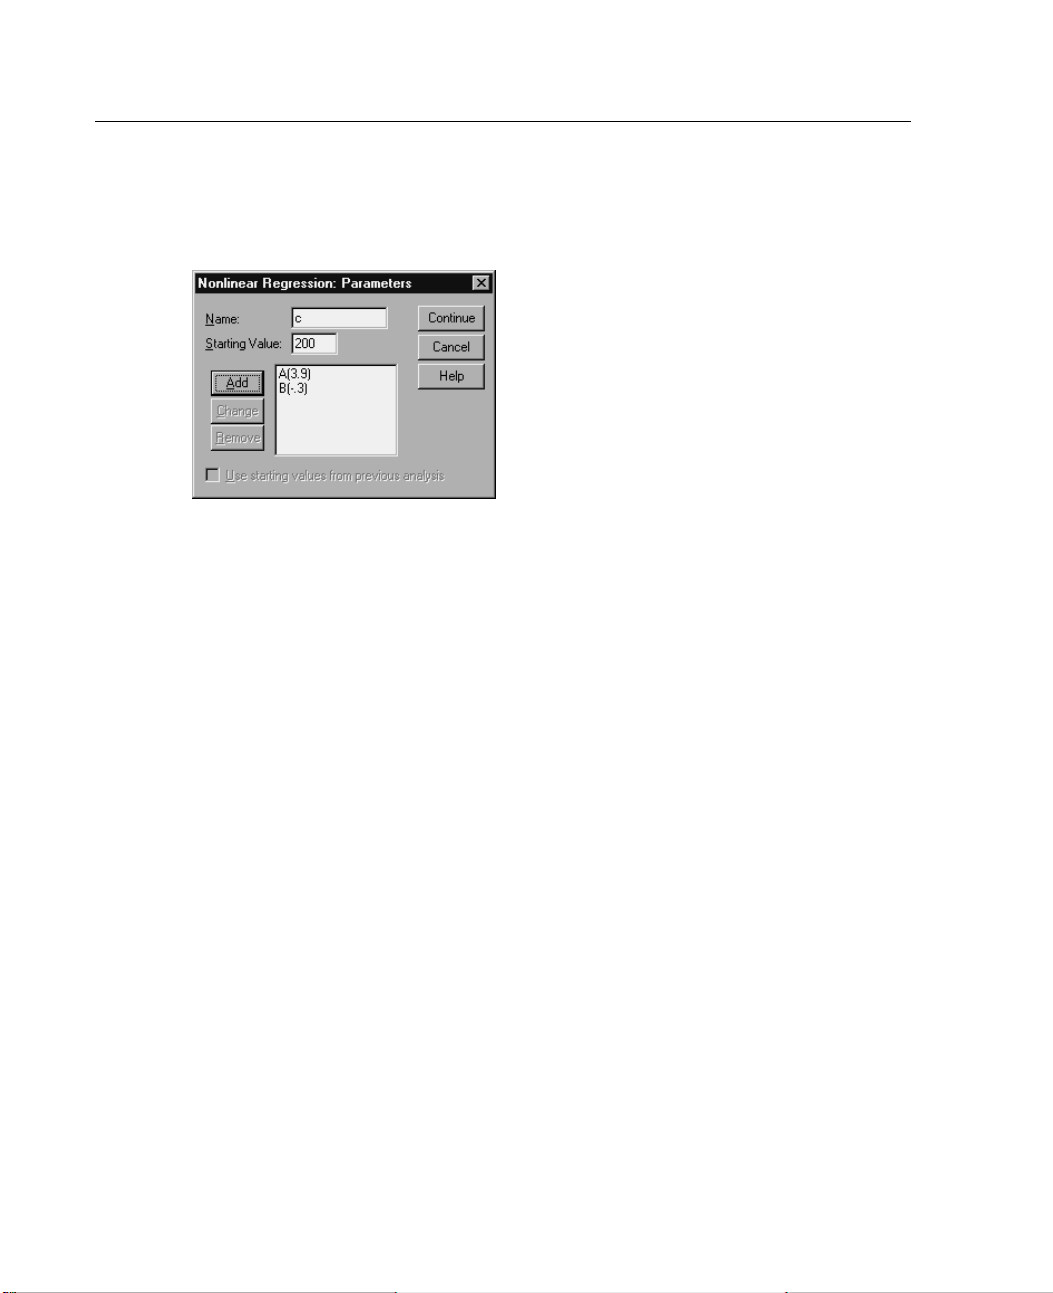
Figure 5-2
Nonlinear Regression Parameters dialog box
Parameters are the parts of your model that the Nonlinear Regression procedure
estimates. Parameters can be additive constants, multiplicative coefficients,
exponents, or values used in evaluating functions. All parameters that you have
defined will appear (with their initial values) on the Parameters list in the main
dialog box.
Name. You must specify a name for each parameter. This name must be a valid
SPSS variable name and must be the name used in the model expression in the main
dialog box.
Starting Value. Allows you to specify a starting value for the parameter, preferably
as close as possible to the expected final solution. Poor starting values can result in
failure to converge or in convergence on a solution that is local (rather than global) or
is physically impossible.
gression Parameters
Use starting values from previous analysis. If you have already run a nonlinear
regression from this dialog box, you can select this option to obtain the initial values
of parameters from their values in the previous run. This permits you to continue
searching when the algorithm is converging slowly. (The initial starting values will
still appear on the Parameters list in the main dialog box.)
Note: This selection persists in this dialog box for the rest of your session. If you
change the model, be sure to deselect it.
Page 45
35
Nonlinear Re
The table be
regression models. A model selected at random is not likely to fit your data well.
Appropriate starting values for the parameters are necessary, and some models require
constraint
Tab l e 5- 1
Example mod
Name Model expression
AsymptoticRegression b1+b2*exp(b3*x)
Asymptotic Regression b1 –( b2 *( b3 ** x ))
Density ( b1 + b2 * x )**(–1/ b3 )
Gauss b1 *(1– b3 *exp( –b2 * x **2))
Gompertz b1 *exp( –b2 * exp( –b3 * x ))
Johnson-Schumacher b1 *exp( –b2 / ( x + b3))
Log-Modified (b1+b3*x)**b2
Log-Logistic b1–ln(1+b2*exp(–b3*x))
Metcherlich Law of Diminishing
Returns
MichaelisMenten b1*x/(x+b2)
Morgan-Mercer-Florin (b1*b2+b3*x**b4)/(b2+x**b4)
Peal-Reed
Ratio of Cubics
RatioofQuadratics (b1+b2*x+b3*x**2)/(b4*x**2)
Richards b1 /((1+ b3 *exp(– b2 * x ))**(1/ b4 ))
Verhulst b1/(1+b3*exp(–b2*x))
Von Bertalanffy ( b1 ** (1 – b4 ) – b2 * exp( –b3 * x )) * * (1/(1 –b4 ))
Weibull b1–b2*exp(–b3*x**b4)
Yield Density (b1 + b2 * x + b3 * x **2)**(–1)
Nonlinear Regr
gression Common Models
low provides example model syntax for many published nonlinear
s in order to converge.
el syntax
b1+b2*exp(–b3*x)
b1 /(1+ b2 *exp(–( b3 * x + b4 * x **2+ b5*x**3)))
( b1 + b2 * x + b3 * x **2+ b4 * x **3)/( b5 * x **3)
ession
Page 46
36
Chapter 5
Nonlinear Re
Figure 5-3
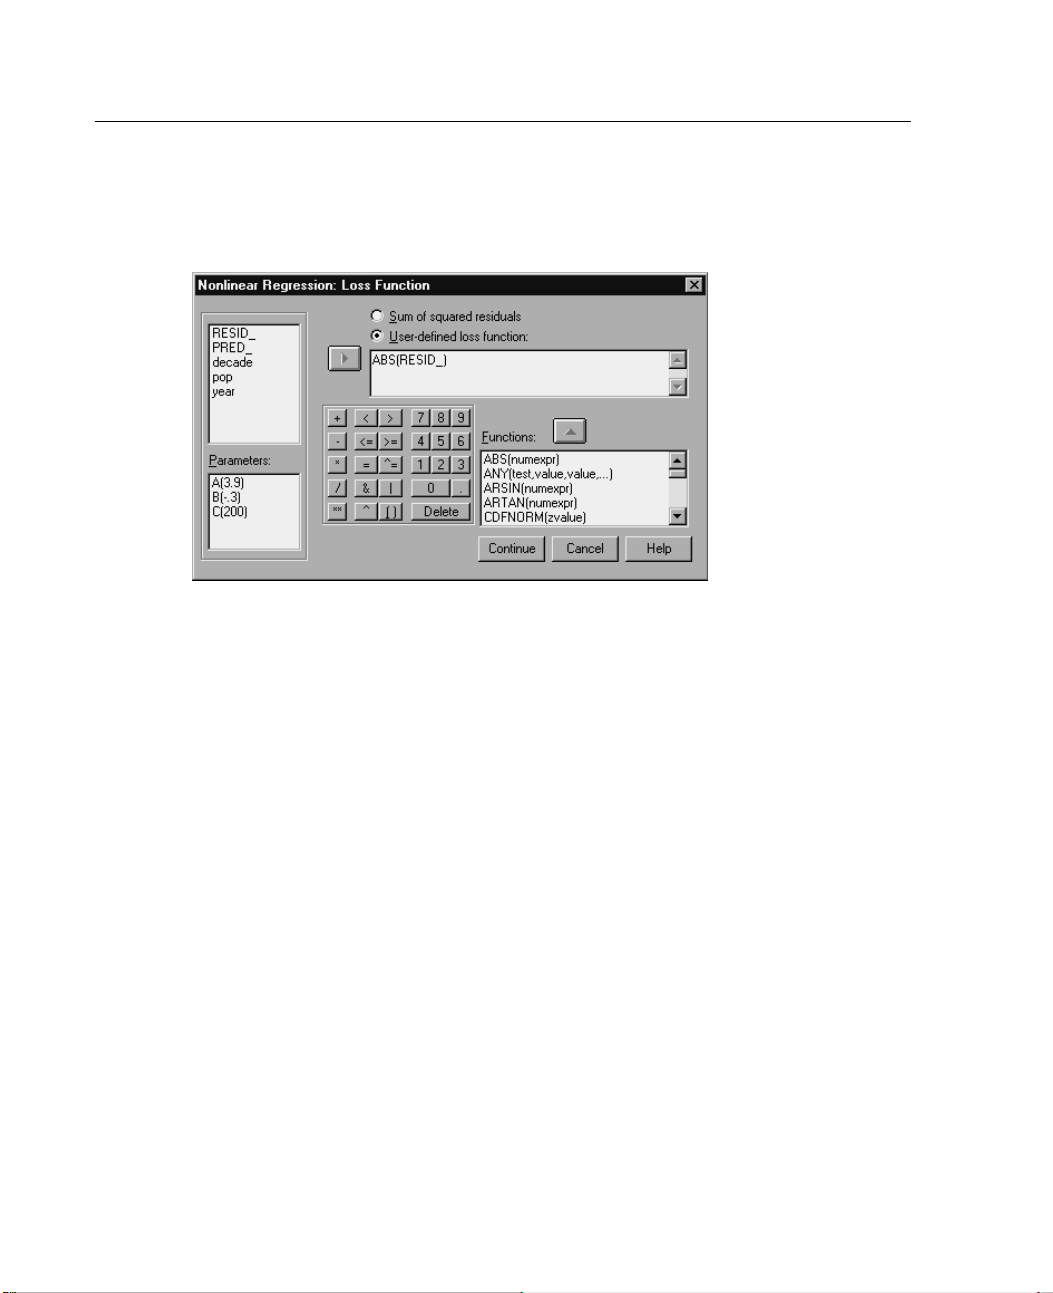
Nonlinear Regression Loss Function dialog box
The loss function in nonlinear regression is the function that is minimized by the
algorithm. Select either Sum of squared residuals to minimize the sum of the squared
residua
If you select
(across all cases) should be minimized by the choice of parameter values.
Most loss functions involve the special variable RESID_, which represents the
residual. (The default Sum of squared residuals loss function could be entered
explic
function, it is equal to the dependent variable minus the residual.
It is possible to specify a conditional loss function using conditional logic.
gression Loss Function
User-defined loss function to minimize a different function.
ls or
User-defined loss function, you must define the loss function whose sum
RESID_**2.)Ifyouneedtousethepredictedvalueinyourloss
itly as
You can
either type an expression in the User-defined loss function field or paste
components of the expression into the field. String constants must be enclosed in
quotation marks or apostrophes, and numeric constants must be typed in American
t, with the dot as a decimal delimiter.
forma
Page 47
37
Nonlinear Re
Figure 5-4
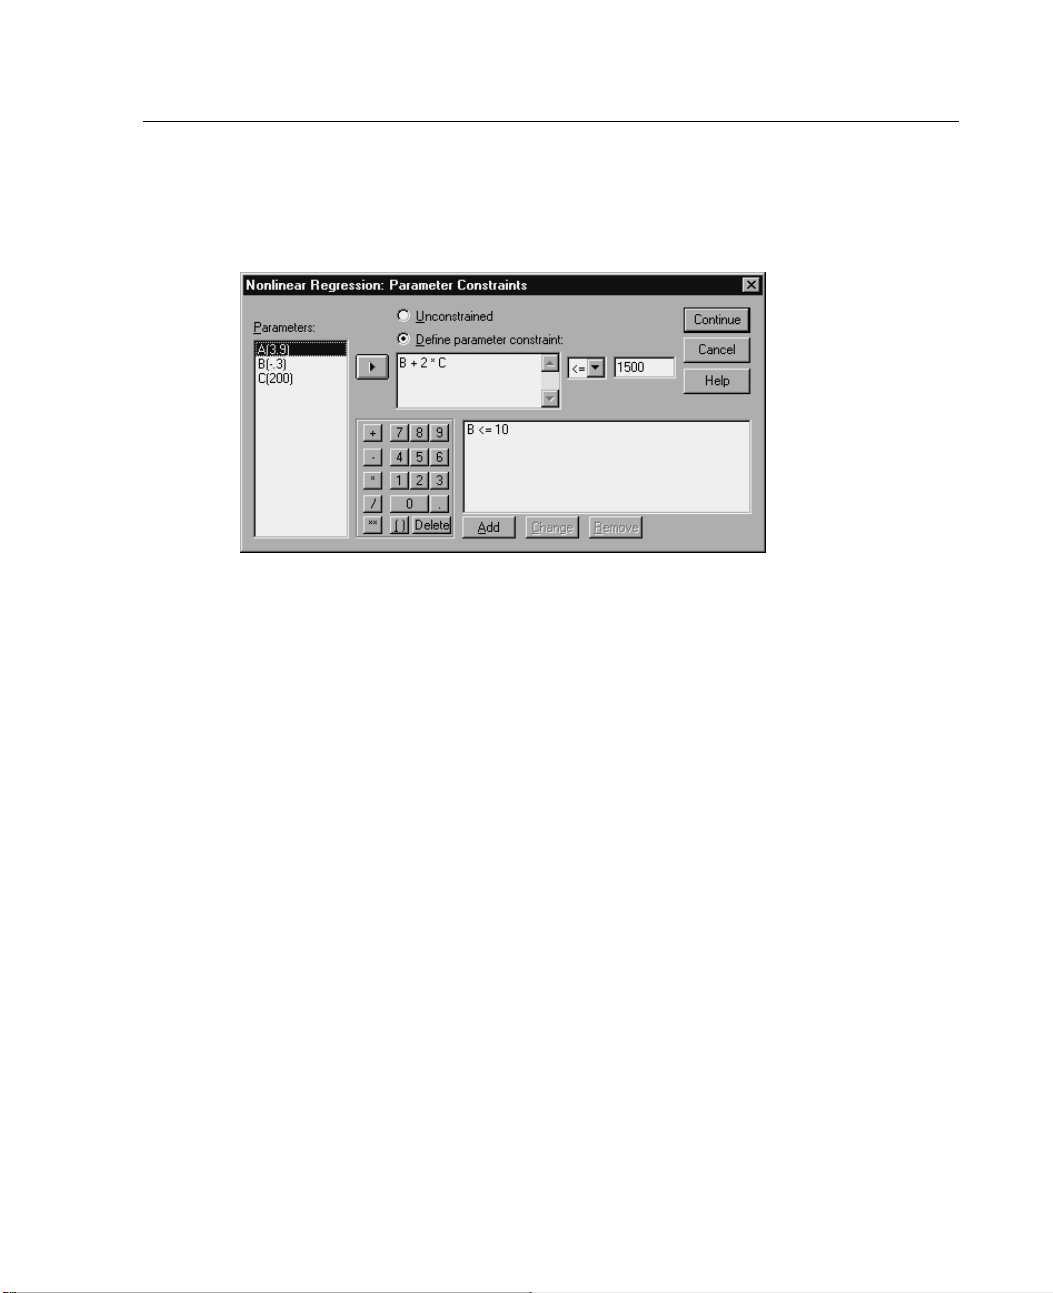
Nonlinear Regression Parameter Constraints dialog box
A constraint is a restriction on the allowable values for a parameter during the
iterative search for a solution. Linear expressions are evaluated before a step is taken,
so you can use linear constraints to prevent steps that might result in overflows.
Nonlinear expressions are evaluated after a step is taken.
Each equation or inequality requires the following elements:
An expression involving at least one parameter in the model. Type the expression
or use the keypad, which allows you to paste numbers, operators, or parentheses
into the expression. You can either type in the required parameter(s) along with
the rest of the expression or paste from the Parameters list at the left. You cannot
use ordinary variables in a constraint.
One of the three logical operators <=, =, or >=.
A numeric constant, to which the expression is compared using the logical
operator. Type the constant. Numeric constants must be typed in American
format, with the dot as a decimal delimiter.
gression Parameter Constraints
Nonlinear Regr
ession
Page 48
38
Chapter 5
Nonlinear Re
Figure 5-5
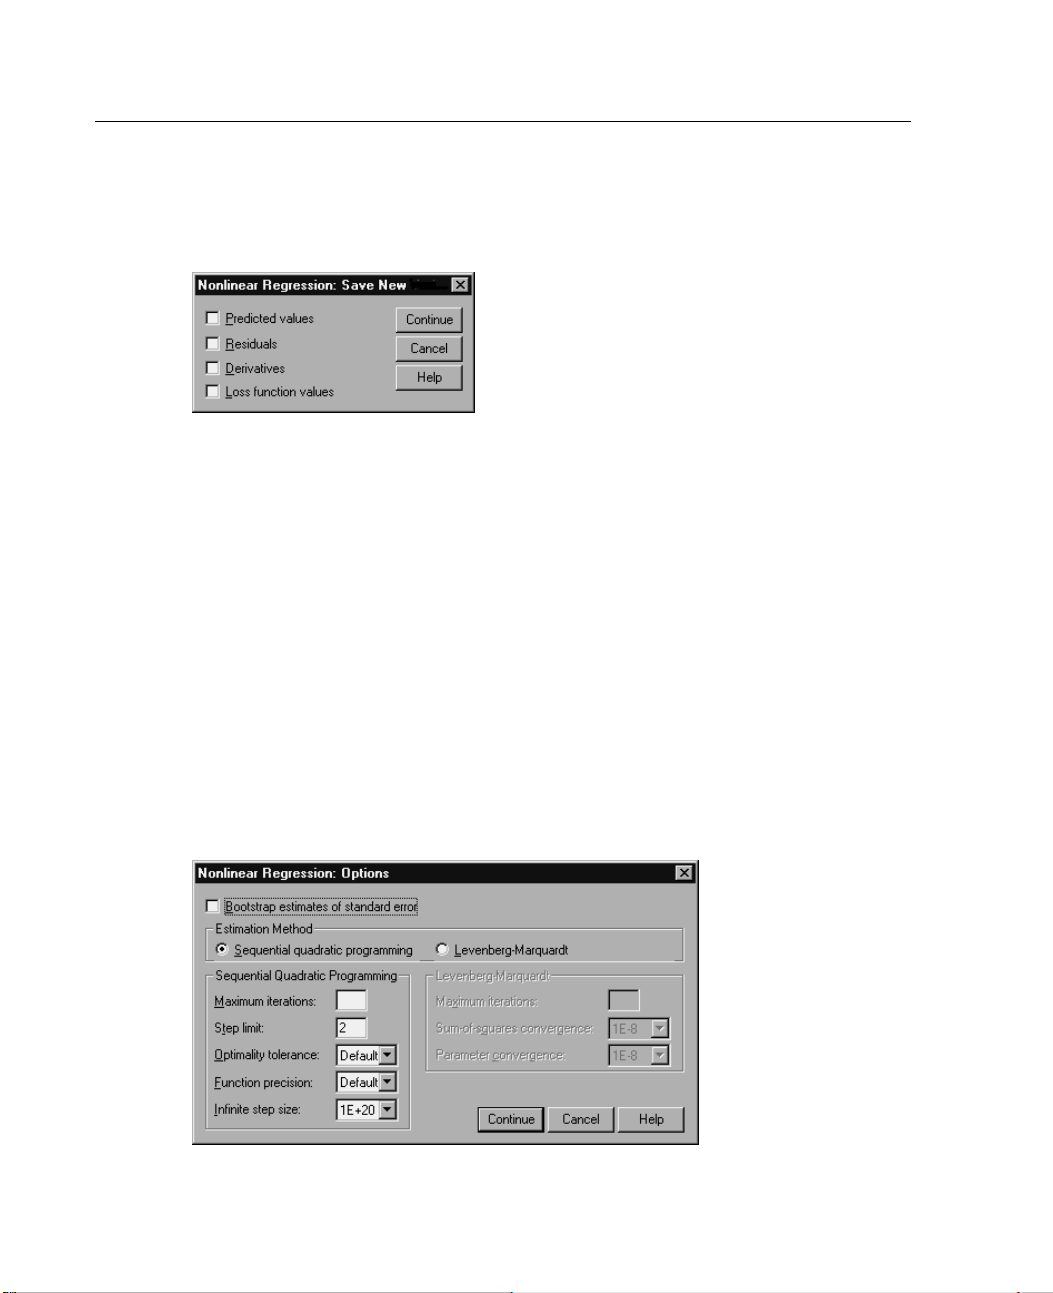
Nonlinear Regression Save New Variables dialog box
You can sav
Predicted values, Residuals, Derivatives, and Loss function values. These variables
can be used in subsequent analyses to test the fit of the model or to identify problem
cases.
Predict
Residua
Derivati
are created by prefixing 'd.' to the first six characters of parameter names.
Loss Function Values. This option is available if you specify your own loss
function. The variable name loss_ is assigned to the values of the loss function.
gression Save New Variables
e a number of new variables to your active data file. Available options are
ed Values.
ls.
ves.
Saves predicted values with the variable name pred_.
Saves residuals with the variable name resid.
One derivative is saved for each model parameter. Derivative names
Nonlinea
Figure 5-6
Nonlinear Regression Options dialog box
r Regression Options
Page 49
39
Nonlinear Regr
ession
Options allow you to control various aspects of your nonlinear regression analysis:
Bootstrap Estimates. A method of estimating the standard error of a statistic using
repeated sa
mples from the original data set. This is done by sampling (with
replacement) to get many samples of the same size as the original data set. The
nonlinear equation is estimated for each of these samples. The standard error of each
parameter e
stimate is then calculated as the standard deviation of the bootstrapped
estimates. Parameter values from the original data are used as starting values for each
bootstrap sample. This requires the sequential quadratic programming algorithm.
Estimatio
n Method.
Allows you to select an estimation method, if possible. (Certain
choices in this or other dialog boxes require the sequential quadratic programming
algorithm.) Available alternatives include Sequential quadratic programming and
Levenber
Sequent
g-Marquardt.
ial Quadratic Programming.
This method is available for constrained and
unconstrained models. Sequential quadratic programming is used automatically
if you specify a constrained model, a user-defined loss function, or bootstrapping.
You can en
ter new values for Maximum iterations and Step limit, and you can
change the selection in the drop-down lists for Optimality tolerance, Function
precision, and Infinite step size.
Levenberg-Marquardt. This is the default algorithm for unconstrained models.
The Leve
nberg-Marquardt method is not available if you specify a constrained
model, a user-defined loss function, or bootstrapping. You can enter new values
for Maximum iterations, and you can change the selection in the drop-down lists
for Sum
-of-squares convergence and Parameter convergence.
Interpreting Nonlinear Regression Results
Nonlinear regression problems often present computational difficulties:
The choice of initial values for the parameters influences convergence. Try to
choose initial values that are reasonable and, if possible, close to the expected
olution.
final s
Somet
imes one algorithm performs better than the other on a particular problem.
In the Options dialog box, select the other algorithm if it is available. (If you
specify a loss function or certain types of constraints, you cannot use the
berg-Marquardt algorithm.)
Leven
Page 50
40
Chapter 5
When iteration stops only because the maximum number of iterations has
occurred, t
values from previous analysis
he “final” model is probably not a good solution. Select
in the Parameters dialog box to continue the iteration
Use starting
or, better yet, choose different initial values.
Models that require exponentiation of or by large data values can cause overflows
or underflo
ws (numbers too large or too small for the computer to represent).
Sometimes you can avoid these by suitable choice of initial values or by imposing
constraints on the parameters.
NLR Comman
The SPSS co
Nameafil
Specify m
specifyasegmentedmodel.
Supply your own derivatives rather than use those calculated by the program.
Specify the number of bootstrap samples to generate.
Specify additional iteration criteria, including setting a critical value for derivative
checking and defining a convergence criterion for the correlation between the
residuals
Additional criteria for the
you to:
Specify the maximum number o f minor iterations allowed within each major
iteration.
Set a critical value for derivative checking.
Set a step limit.
Specify a crash tolerance to determine if initial values are within their specified
bounds.
See the SPSS Command Syntax Reference for complete syntax information.
d Additional Features
mmand language also allows you to:
e from which to read initial values for parameter estimates.
ore than one model statement and loss function. This makes it easier to
and the derivatives.
CNLR (constrained nonlinear regression) command allow
Page 51
Chapter
6
Weight Estim
Standard linear regression models assume that variance is constant within the
population
are high on some attribute show more variability than cases that are low on that
attribute—linear regression using ordinary least squares (OLS) no longer provides
optimal mo
another variable, the Weight Estimation procedure can compute the coefficients of
a linear regression model using weighted least squares (WLS), such that the more
precise o
determining the regression coefficients. The Weight Estimation procedure tests a
range of weight transformations and indicates which will give the best fit to the data.
Example.
prices? Because stocks with higher share values often show more variability than
those with low share values, ordinary least squares will not produce optimal estimates.
Weight e
of price changes in calculating the linear model.
under study. When this is not the case—for example, when cases that
del estimates. If the differences in variability can be predicted from
bservations (that is, those with less variability) are given greater weight in
What are the effects of inflation and unemployment on changes in stock
stimation allows you to account for the effect of share price on the variability
ation
Statistics. Log-likelihood values for each power of the weight source variable
, multiple R, R-squared, adjusted R-squared, ANOVA table for WLS model,
tested
unstandardized and standardized p arameter estimates, and log-likelihood for the
WLS model.
Data. T
variables, such as religion, major, or region of residence, need to be recoded to binary
(dummy) variables or other types of contrast variables. The weight variable should be
quant
Assumptions. For each value of the independent variable, the distribution of the
dependent variable must be normal. The relationship between the dependent variable
and ea
independent. The variance of the dependent variable can vary across levels of the
he dependent and independent variables should be quantitative. Categorical
itative and should be related to the variability in the dependent variable.
ch independent variable should be linear, and all observations should be
41
Page 52
42
Chapter 6
independent variable(s), but the differences must be predictable based on the weight
variable.
Related pr o
cedures.
The Explore procedure can be used to screen your data. Explore
provides tests for normality and homogeneity of variance, as well as graphical
displays. If your dependent variable seems to have equal variance across levels
of independ
ent variables, you can use the Linear Regression procedure. If your
data appear to violate an assumption (such as normality), try transforming them.
If your data are not related linearly and a transformation does not help, use an
alternate
model in the Curve Estimation procedure. If your dependent variable is
dichotomous—for example, whether a particular sale is completed or whether an item
is defective—use the Logistic Regression procedure. If your dependent variable is
censored
—for example, survival time after surgery—use Life Tables, Kaplan-Meier,
or Cox Regression, available in the SPSS Advanced Models option. If your data
are not independent—for example, if you observe the same person under several
ons—use the Repeated Measures procedure, available in the SPSS Advanced
conditi
Models option.
ng a Weight Estimation Analysis
Obtaini
E From th
Analyze
e menus choose:
Regression
Weight Estimation...
Page 53
43
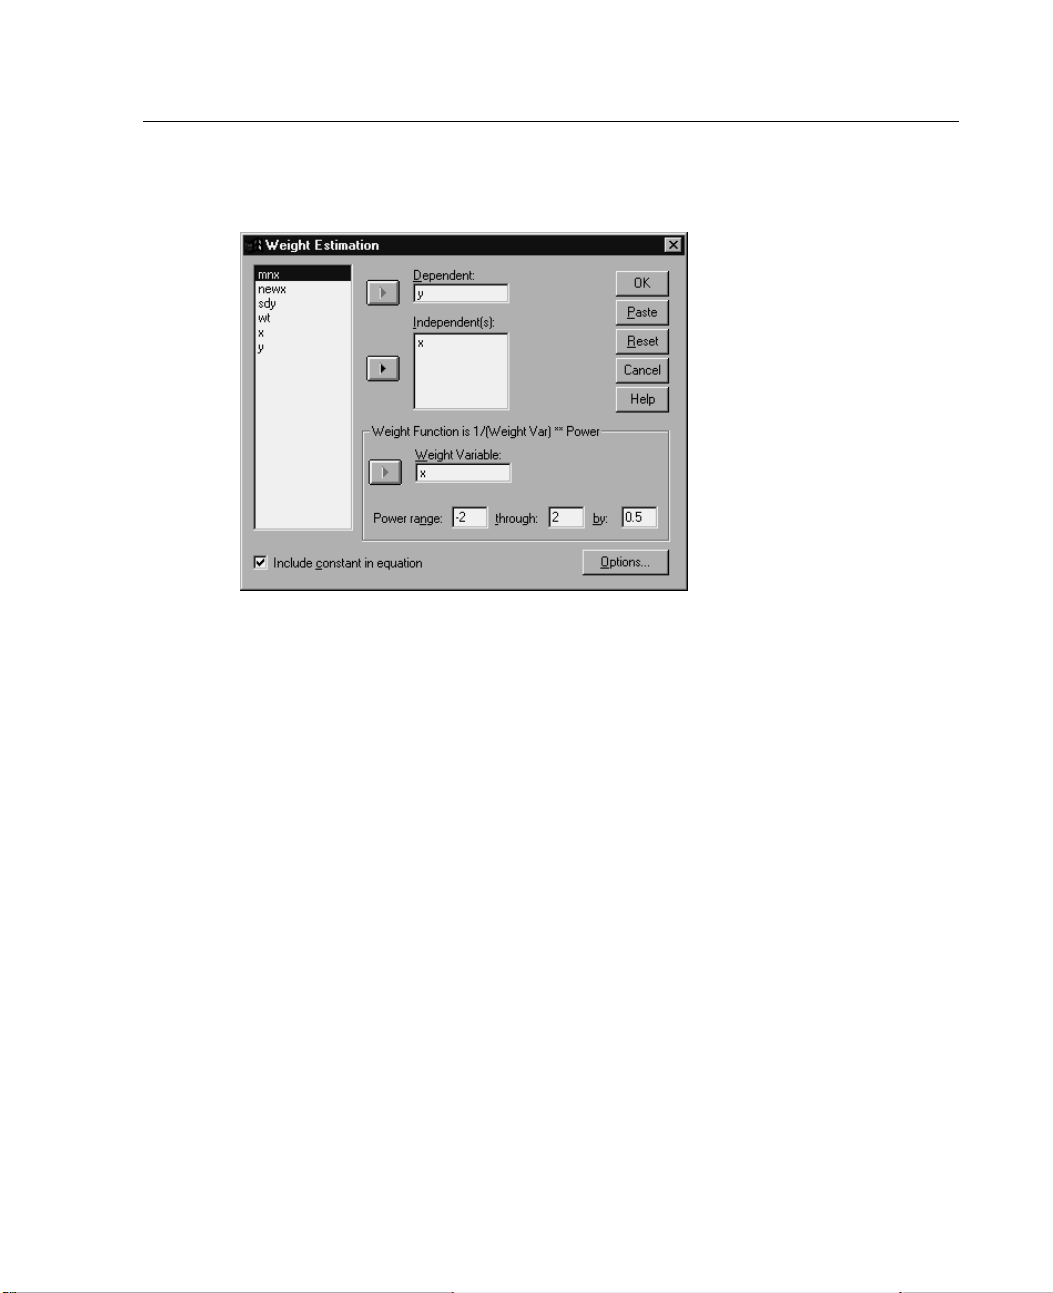
Figure 6-1
Weight Estimation dialog box
E Select one dependent variable.
E Select one or more independent variables.
Weight Estimat
ion
E Select the variable that is the source of heteroscedasticity as the weight variable.
Weight Variable. The data are weighted by the reciprocal of this variable raised to
a power. The regression equation is calculated for each of a specified range of
power values and indicates the power that maximizes the log-likelihood function.
Power Range. This is used in conjunction with the weight variable to compute
weights. Several regression equations will be fit, one for each value in the power
range. The values entered in the Power range test box and the through text box
must be between -6.5 and 7.5, inclusive. The power values range from the low to
high value, in increments determined by the value specified. The total number of
values in the power range is limited to 150.
Page 54
44
Chapter 6
Weight Estim
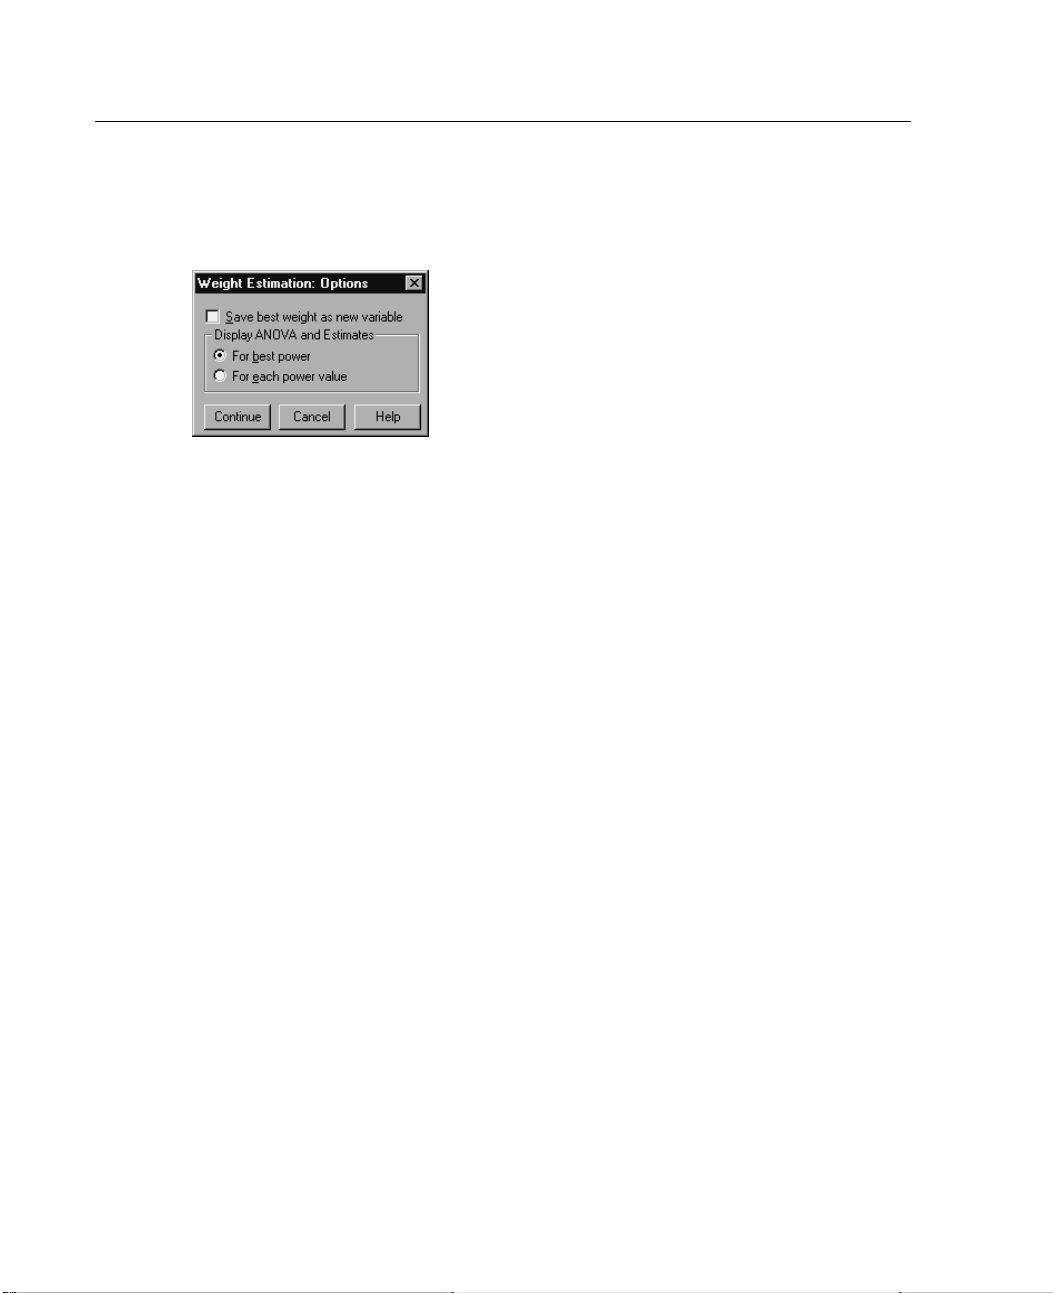
Figure 6-2
Weight Estimation Options dialog box
You can specify options for your weight estimation analysis:
Save b est weight as new variable. Adds the weight variable to the active file. This
variable is called WGT_n,wheren is a number chosen to give the variable a unique
name.
Display ANOVA and Estimates. Allows you to control how statistics are displayed in the
output. Available alternatives are For best power and For each power value.
ation Options
WLS Command Additional Features
The SPSS command language also allows you to:
Provideasinglevalueforthepower.
Specify a list of power values, or mix a range of values with a list of values for
the power.
See the SPSS Command Syntax Reference for complete syntax information.
Page 55
Chapter
7
Two-Stage Le
Regression
Standard l
uncorrelated with the independent variable(s). When this is not the case (for example,
when relationships between variables are bidirectional), linear regression using
ordinary l
least-squares regression uses instrumental variables that are uncorrelated with the
error terms to compute estimated values of the problematic predictor(s) (the first
stage), a
of the dependent variable (the second stage). Since the computed values are based
on variables that are uncorrelated with the errors, the results of the two-stage model
are opti
Example. Is the demand for a commodity related to its price and consumers’ incomes?
The difficulty in this model is that price and demand have a reciprocal effect on each
other. T
two-stage least-squares regression model might use consumers’ incomes and lagged
price to calculate a proxy for price that is uncorrelated with the measurement errors in
demand
whichisthenestimated.
inear regression models assume that errors in the dependent variable are
east squares (OLS) no longer provides optimal model estimates. Two-stage
nd then uses those computed values to estimate a linear regression model
mal.
hat is, price can influence demand and demand can also influence price. A
. This proxy is substituted for price itself in the originally specified model,
ast-Squares
Statistics. For each model: standardized and unstandardized regression coefficients,
2
le R, R
multip
predicted values, and residuals. Also, 95% confidence intervals for each regression
coefficient, and correlation and covariance matrices of parameter estimates.
The dependent and independent variables should be quantitative. Categorical
Data.
variables, such as religion, major, or region of residence, need to be recoded to binary
(dummy) variables or other types of contrast variables. Endogenous explanatory
ables should be quantitative (not categorical).
vari
, adjusted R2, standard error of the estimate, analysis-of-variance table,
45
Page 56
46
Chapter 7
Assumptions. For each value of the independent variable, the distribution of the
dependent variable must be normal. The variance of the distribution of the dependent
variable sh
ould be constant for all values of the independent variable. The relationship
between the dependent variable and each independent variable should be linear.
Related procedu res. If you believe that none of your predictor variables is correlated
with the err
ors in your dependent variable, you can use the Linear Regression
procedure. If your data appear to violate one of the assumptions (such as normality
or constant variance), try transforming them. If your data are not related linearly
and a trans
formation does not help, use an alternate model in the Curve Estimation
procedure. If your dependent variable is dichotomous, such as whether a particular
sale is completed or not, use the Logistic Regression procedure. If your data are
not indep
endent—for example, if you observe the same person under several
conditions—use the Repeated Measures procedure, available in the SPSS Advanced
Models option.
Obtaining a Two-Stage Least-Squares Regression Analysis
E From the menus choose:
Analyze
Regression
2-Stage Least Squares...
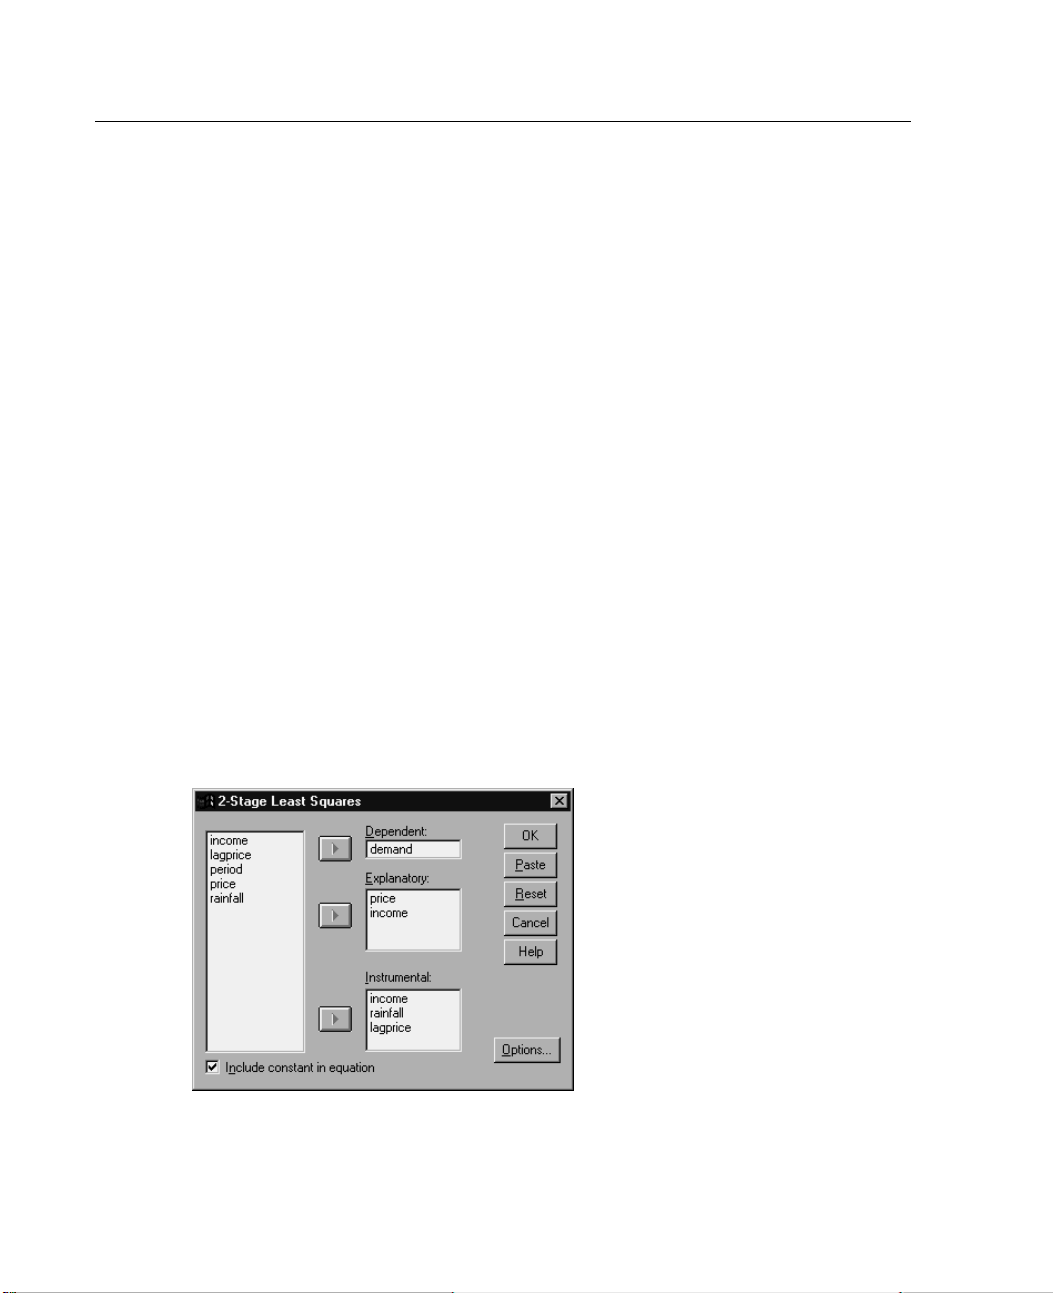
Figure 7-1
2-Stage Least Squares dialog box
E Select one dependent variable.
Page 57
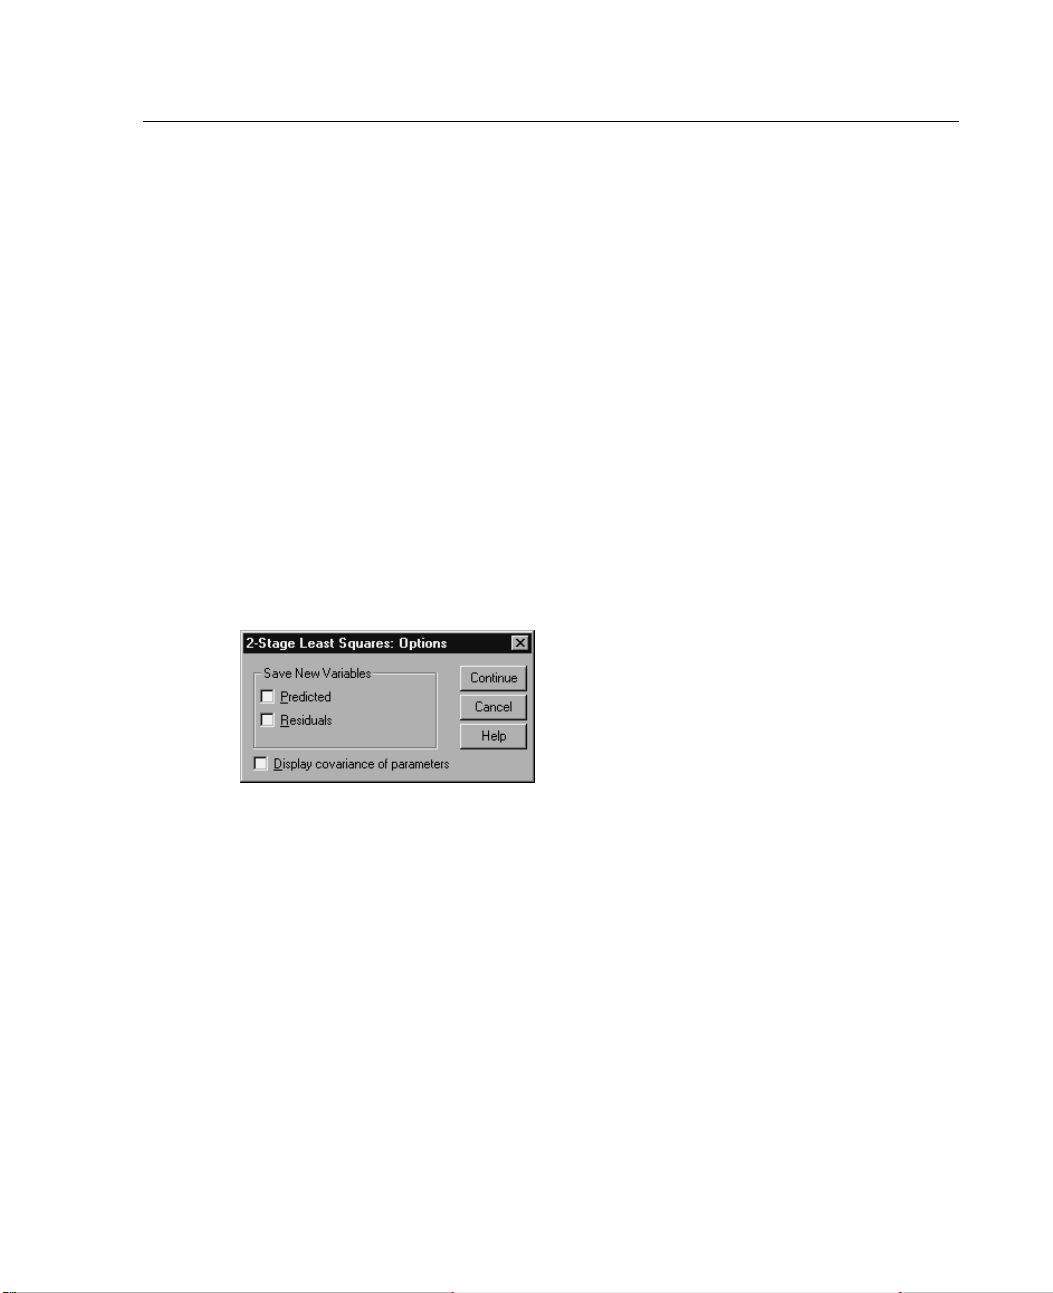
47
Two-Stage Leas
E
Select one or more explanatory (predictor) variables.
E Select one or more instrumental variables.
Instrumental. These are the variables used to compute the predicted values for the
endogenous v
ariables in the first stage of two-stage least squares analysis. The
same variables may appear in both the Explanatory and Instrumental list boxes.
The number of instrumental variables must be at least as many as the number of
explanator
y variables. If all explanatory and instrumental variables listed are the
same, the results are the same as results from the Linear Regression procedure.
Explanator
y variables not specified as instrumental are considered endogenous.
Normally, all of the exogenous variables in the Explanatory list are also specified as
instrumental variables.
Two-Stage Least-Squares Regression Options
Figure 7-2
2-Stage Least Squares Options dialog box
t-Squares Regression
You can select the following options for your analysis:
Save New Variables. Allows you to add new variables to your active file. Available
options
Display covariance of parameters. Allows you to print the covariance matrix of the
are Predicted and Residuals.
parameter estimates.
2SLS Command Additional Features
The SPSS command language also allows you to estimate multiple equations
simultaneously. See the SPSS Command Syntax Reference for complete syntax
ation.
inform
Page 58
Page 59
Appendix
A
Categorical
Schemes
S procedures, you can request automatic replacement of a categorical
ded, usually on the
n from the grand mean.
(1/k 1/k
( 1–1/k –1/k
(–1/k 1–1/k
..
..
(–1/k –1/k
Deviatio
In many SPS
independent variable with a set of contrast variables, which will then be entered or
removed from an equation as a block. Youcan specify how the set of contrast variables
is to be co
illustrates how d ifferent contrast types requested on CONTRAST actually work.
n
Deviatio
mean
df(1)
df(2)
df(k–1)
Variable Coding
CONTRAST subcommand. This appendix explains and
In matrix terms, these contrasts have the form:
...
...
...
...
1/k 1/k )
–1/k –1/k )
–1/k –1/k )
1–1/k –1/k )
k is the number of categories for the independent variable and the last category
where
is omitted by default. For example, the deviation contrasts for an independent variable
with three categories are as follows:
( 1/3 1/3 1/3 )
( 2/3 –1/3 –1/3 )
( –1/3 2/3 –1 /3 )
49
Page 60
50
Appendix A
Simple
To omit a category other than the last, specify the number of the omitted category in
parentheses after the DEVIATION keyword. For example, the following subcommand
obtains the
/CONTRAST(FACTOR)=DEVIATION(2)
deviations for the first and third categories and omits the second:
Suppose that factor has three categories. The resulting contrast matrix will be
( 1/3 1/3 1/3 )
( 2/3 –1/3 –1/3 )
( –1/3 –1/3 2/3 )
Simple contrasts. Compares each level of a factor to the last. The general matrix
form is
mean
df(1) ( 1 0
df(2) ( 0 1
df(k–1) ( 0 0
(1/k 1/k
..
..
...
...
...
...
1/k 1/k )
0–1)
0–1)
1–1)
where k is the number of categories for the independent variable. For example, the
e contrasts for an independent variable with four categories are as follows:
simpl
( 1/4 1/4 1/4 1/4 )
(1 0 0 –1)
(0 1 0 –1)
(0 0 1 –1)
se another category instead of the last as a reference category, specify in
To u
parentheses after the
SIMPLE keyword the sequence number of the reference
category, which is not necessarily the value associated with that category. For
Page 61
51
Helmert
Categorical Va
riable Coding Schemes
example, the following CONTRAST subcommand obtains a contrast matrix that omits
the second category:
/CONTRAST(FACTOR) = SIMPLE(2)
Suppose that factor has four categories. The resulting contrast matrix will be
( 1/4 1/4 1/4 1/4 )
(1 –1 0 0)
(0 –1 1 0)
(0 –1 0 1)
Helmert c
ontrasts.
Compares categories of an independent variable with the mean of
the subsequent categories. The general matrix form is
mean
df(1) ( 1
df(2) ( 0 1
df(k–2) ( 0 0 1 –1/2 –1/2
df(k–1) ( 0 0
(1/k 1/k
–1/(k–1)
..
..
...
...
...
...
1/k 1/k )
–1/(k–1) –1/(k–1) )
–1/(k–2) –1/(k–2) )
1–1)
where k is the number of categories of the independent variable. For example, an
independent variable with four categories has a Helmert contrast matrix of the
wing form:
follo
( 1/4 1/4 1/4 1/4 )
( 1 –1/3 –1/3 –1/3 )
( 0 1 –1/2 –1/2 )
(0 0 1 –1)
Page 62
52
Appendix A
Difference
Difference
variable with the mean of the previous categories of the variable. The general matrix
form is
df(k–1)
where k is the number of categories for the independent variable. For example, the
differe
Polynomial
or reverse Helmert contrasts.
mean
df(1) ( –1 1 0
df(2) ( –1/2 –1/2 1
..
..
(1/k 1/k 1/k
( –1/(k–1) –1/(k–1) –1/(k–1)
Compares categories of an independent
...
...
...
...
1/k )
0)
0)
1)
nce contrasts for an independent variable with four categories are as follows:
( 1/4 1/4 1/4 1/4 )
(–1 1 0 0)
( –1/2 –1/2 1 0 )
( –1/3 –1/3 –1/3 1 )
Orthogonal polynomial contrasts. The first degree of freedom contains the linear effect
s all categories; the second degree of freedom, the quadratic effect; the third
acros
degree of freedom, the cubic; and so on, for the higher-order effects.
You can specify the spacing between levels of the treatment measured by the given
gorical variable. Equal spacing, which is the default if you omit the metric, can be
cate
specified as consecutive integers from 1 to k,wherek is the number of categories. If
the variable drug has three categories, the subcommand
/CONTRAST(DRUG)=POLYNOMIAL
is the same as
TRAST(DRUG)=POLYNOMIAL(1,2,3)
/CON
Page 63
53
Categorical Va
riable Coding Schemes
Equal spacing is not always n ecessary, however. For example, suppose that
drug represents different dosages of a drug given to three groups. If the dosage
administer
ed to the second group is twice that given to the first group and the dosage
administered to the third group is three times that given to the first group, the
treatment categories are equally spaced, and an appropriate metric for this situation
consists o
/CONTRAST(DRUG)=POLYNOMIAL(1,2,3)
f consecutive integers:
If, however, the dosage administered to the second group is four times that given to
the first g
roup, and the dosage administered to the third group is seven times that
given to the first group, an appropriate metric is
/CONTRAST
In either c
(DRUG)=POLYNOMIAL(1,4,7)
ase, the result of the contrast specification is that the first degree of freedom
for drug contains the linear effect of the dosage levels and the second degree of
freedom contains the quadratic effect.
Polynomi
al contrasts are especially useful in tests of trends and for investigating
the nature of response surfaces. You can also use polynomial contrasts to perform
nonlinear curve fitting, such as curvilinear regression.
Repeated
Compares adjacent levels of an independent variable. The general matrix form is
mean
df(1) ( 1 –1 0
df(2) ( 0 1 –1
df(k–1) ( 0 0 0
(1/k 1/k 1/k
..
..
...
...
...
...
1/k 1/k )
00)
00)
1–1)
Page 64
54
Appendix A
Special
where k is the number of categories for the independent variable. For example, the
repeated contrasts for an independent variable with four categories are as follows:
( 1/4 1/4 1/4 1/4 )
(1 –1 0 0)
(0 1 –1 0)
(0 0 1 –1)
These contrasts are useful in profile analysis and wherever difference scores are
needed.
A user-defined contrast. Allows entry of special contrasts in the form of square
matrices
independent variable. For
with as many rows and columns as there are categories of the given
MANOVA and LOGLINEAR, the first row entered is always
the mean, or constant, effect and represents the set of weights indicating how to
average
other independent variables, if any, over the given variable. Generally, this
contrastisavectorofones.
The remaining rows of the matrix contain the special contrasts indicating the
d comparisons between categories of the variable. Usually, orthogonal contrasts
desire
are the most useful. Orthogonal contrasts are statistically independent and are
nonredundant. Contrasts are orthogonal if:
For each row, contrast coefficients sum to 0.
The products of corresponding coefficients for all pairs of disjoint rows also
sum to 0.
For example, suppose that treatment has four levels and that you want to compare the
various levels of treatment with each other. An appropriate special contrast is
( 1 1 1 1 ) weights for mean calculation
st
( 3 –1 –1 –1 ) compare 1
( 0 2 –1 –1 ) compare 2ndwith 3rdand 4
( 0 0 1 –1 ) compare 3rdwith 4
with 2ndthrough 4
th
th
th
Page 65
55
Categorical Va
riable Coding Schemes
which you specify by means of the following CONTRAST subcommand for MANOVA,
LOGISTICREGRESSION,andCOXREG:
/CONTRAST(TREATMNT)=SPECIAL( 1111
3-1-1-1
0 2 -1 -1
001-1)
For LOGLINEAR, you need to specify:
/CONTRAST(T
Each row exce
REATMNT)=BASIS SPECIAL( 1111
3-1-1-1
0 2 -1 -1
001-1)
pt the means row sums to 0. Products of each pair of disjoint rows
sumto0aswell:
Rows 2 and 3: (3)(0) + (–1)(2) + (–1)(–1) + (–1)(–1) = 0
Rows 2 and 4: (3)(0) + (–1)(0) + (–1)(1) + (–1)(–1) = 0
Rows 3 and 4: (0)(0) + (2)(0) + (–1)(1) + (–1)(–1) = 0
The special contrasts need not be orthogonal. However, they must not be linear
combinations of each other. If they are, the procedure reports the linear dependency
and ceases
processing. Helmert, difference, and polynomial contrasts are all
orthogonal contrasts.
Indicator
Indicator
LOGLINEAR or MANOVA. The number of new variables coded is k–1. Cases in the
reference category are coded 0 for all k–1 variables. A case in the ithcategory is
coded 0 fo
variable coding.
Also known as dummy coding, this is not available in
r all indicator variables except the i
th
, which is coded 1.
Page 66
Page 67
Index
asymptotic regression
in Nonlinear Regression, 35
backward elimination
in Logistic Regression, 6
binary logistic regression, 1
cal covariates, 7
categori
cell probabilities tables
in Multinomial Logistic Regression, 18
cells with zero observations
in Multinomial Logistic Regression, 20
classification
in Multino
classification tables
in Multinomial Logistic Regression, 18
confidence intervals
in Multinomial Logistic Regression, 18
constant term
in Linear Re
constrained regression
in Nonlinear Regression, 37
contrasts
in Logistic Regression, 7
convergence criterion
in Multinomi
Cook’s D
in Logistic Regression, 9
correlation matrix
in Multinomial Logistic Regression, 18
covariance matrix
in Multinomi
covariates
in Logistic Regression, 7
mial Logistic Regression, 13
gression, 10
al Logistic Regression, 20
al Logistic Regression, 18
Cox and Snell R-square
in Multinomial Logistic Regression, 18
custom models
in Multinomial Logistic Regression, 15
delta
as correct
density model
in Nonlinear Regression, 35
deviance function
for estimating dispersion scaling value, 21
DfBeta
in Logistic
dispersion scaling value
in Multinomial Logistic Regression, 21
fiducial confidence intervals
in Probit Analysis, 28
forward selection
in Logistic
full factorial models
in Multinomial Logistic Regression, 15
Gauss model
in Nonlinear Regression, 35
Gompertz model
in Nonlinea
goodness of fit
in Multinomial Logistic Regression, 18
ion for cells with zero observations, 20
Regression, 9
Regression, 6
r Regression, 35
57
Page 68
58
Index
Hosmer-Lemeshow goodness-of-fit statistic
in Logistic Regression, 10
intercept
include or exclude, 15
iteration history
in Multinomial Logistic Regression, 20
iterations
in Logistic Regression, 10
in Multinomi
al Logistic Regression, 20
in Probit Analysis, 28
Johnson-Schumacher model
in Nonlinear Regression, 35
leverage values
in Logistic Regression, 9
likelihood
ratio
for estimating dispersion scaling value, 21
goodness of fit, 18
Linear Regression
Two-Stage Least-Squares Regression, 45
weight estimation, 41
Logistic Reg
ression, 3
binary, 1
categorical covariates, 7
classification cutoff, 10
coefficients, 3
command additionalfeatures,11
constant term
,10
contrasts, 7
define selection rule, 6
display options, 10
example, 3
Hosmer-Lemeshow goodness-of-fit statistic, 10
influence meas
ures, 9
iterations, 10
predicted values, 9
probability for stepwise, 10
residuals, 9
saving new variables, 9
set rule, 6
statistics, 3
statistics and plots, 10
string covariates, 7
variable selection methods, 6
log-likelihood
in Multinomia
l Logistic Regression, 18
in Weight Estimation, 41
log-modified model
in Nonlinear Regression, 35
main-effects models
in Multinomial Logistic Regression, 15
McFadden R-sq
uare
in Multinomial Logistic Regression, 18
Metcherlich law of diminishing returns
in Nonlinear Regression, 35
Michaelis Menten model
in Nonlinear Regression, 35
Morgan-Merce
r-Florin model
in Nonlinear Regression, 35
Multinomial Logistic Regression, 13, 18
command additionalfeatures,24
criteria, 20
exporting model information, 23
models, 15
reference category, 17
save, 23
statistics, 18
Nagelkerke R-square
in Multinomial Logistic Regression, 18
nonlinear mode
ls
in Nonlinear Regression, 35
Nonlinear Regression, 31
bootstrap estimates, 38
command additionalfeatures,40
common nonlinear models, 35
conditional log
ic, 33
Page 69
59
Index
derivatives, 38
estimation methods, 38
example, 31
interpretation of results, 39
Levenberg-Marquardt algorithm, 38
loss function, 36
parameter constraints, 37
parameters, 34
predicted val
ues, 38
residuals, 38
save new variables, 38
segmented model, 33
sequential quadratic programming, 38
starting values, 34
statistics, 31
parallelism test
in Probit Analysis, 28
parameter constraints
in Nonlinear Regression, 37
parameter estimates
in Multinomia
l Logistic Regression, 18
Peal-Reed model
in Nonlinear Regression, 35
Pearson chi-square
for estimating dispersion scaling value, 21
goodness of fit, 18
Probit Analysi
s
command additionalfeatures,29
criteria, 28
define range, 27
example, 25
fiducial confidence intervals, 28
iterations, 28
natural response rate, 28
parallelism test, 28
relative median potency, 28
statistics, 25, 28
ratio of quadratics model
in Nonlinear Regression, 35
reference ca
tegory
in Multinomial Logistic Regression, 17
relative me dian potency
in Probit Analysis, 28
Richards model
in Nonlinear Regression, 35
separation
in Multinomial Logistic Regression, 20
singularity
in Multinomial Logistic Regression, 20
step-halving
in Multinomial Logistic Regression, 20
stepwise sele
ction
in Logistic Regression, 6
in Multinomial Logistic Regression, 15
string covariates
in Logistic Regression, 7
Two-Stage Least-Squares Regression, 45
command addit
ional features, 47
covariance o f paramete rs, 47
example, 45
instrumental variables, 45
saving new variables, 47
statistics, 45
Verhulst mode
l
in Nonlinear Regression, 35
Von Bertalanffy model
in Nonlinear Regression, 35
ratio of cubics model
in Nonlinear Reg
ression, 35
Weibull model
in Nonlinear Regression, 35
Page 70
60
Index
Weight Estimation, 41
command additionalfeatures,44
display ANOV
A and estimates, 44
example, 41
iteration history, 44
log-likelihood, 41
save best weights as new variable, 44
statistics, 41
yield density model
in Nonlinear Regression, 35
 Loading...